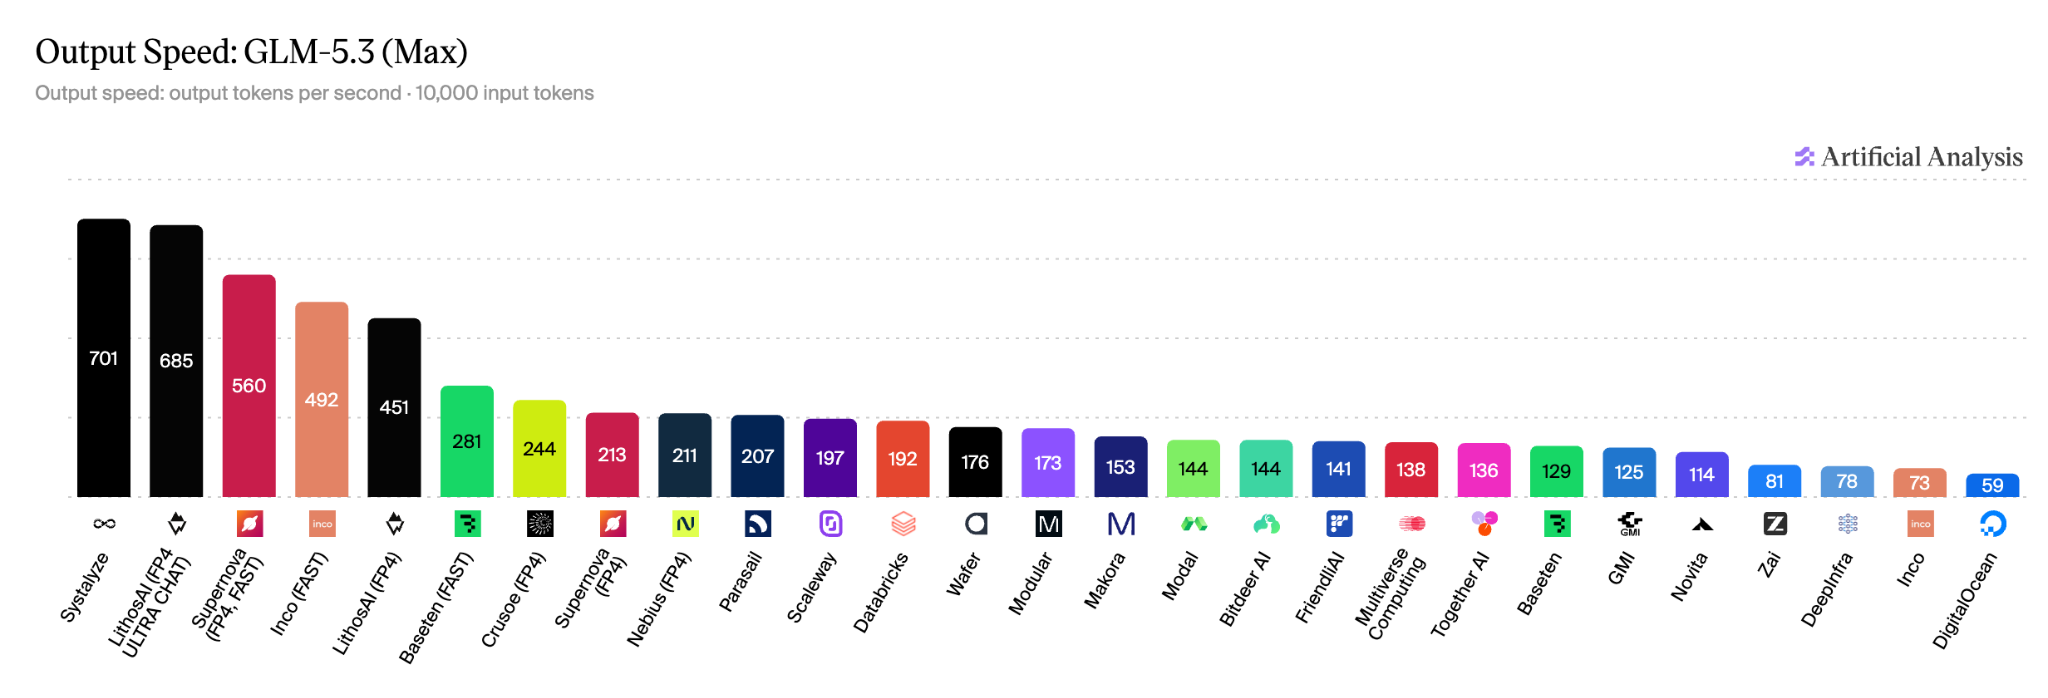
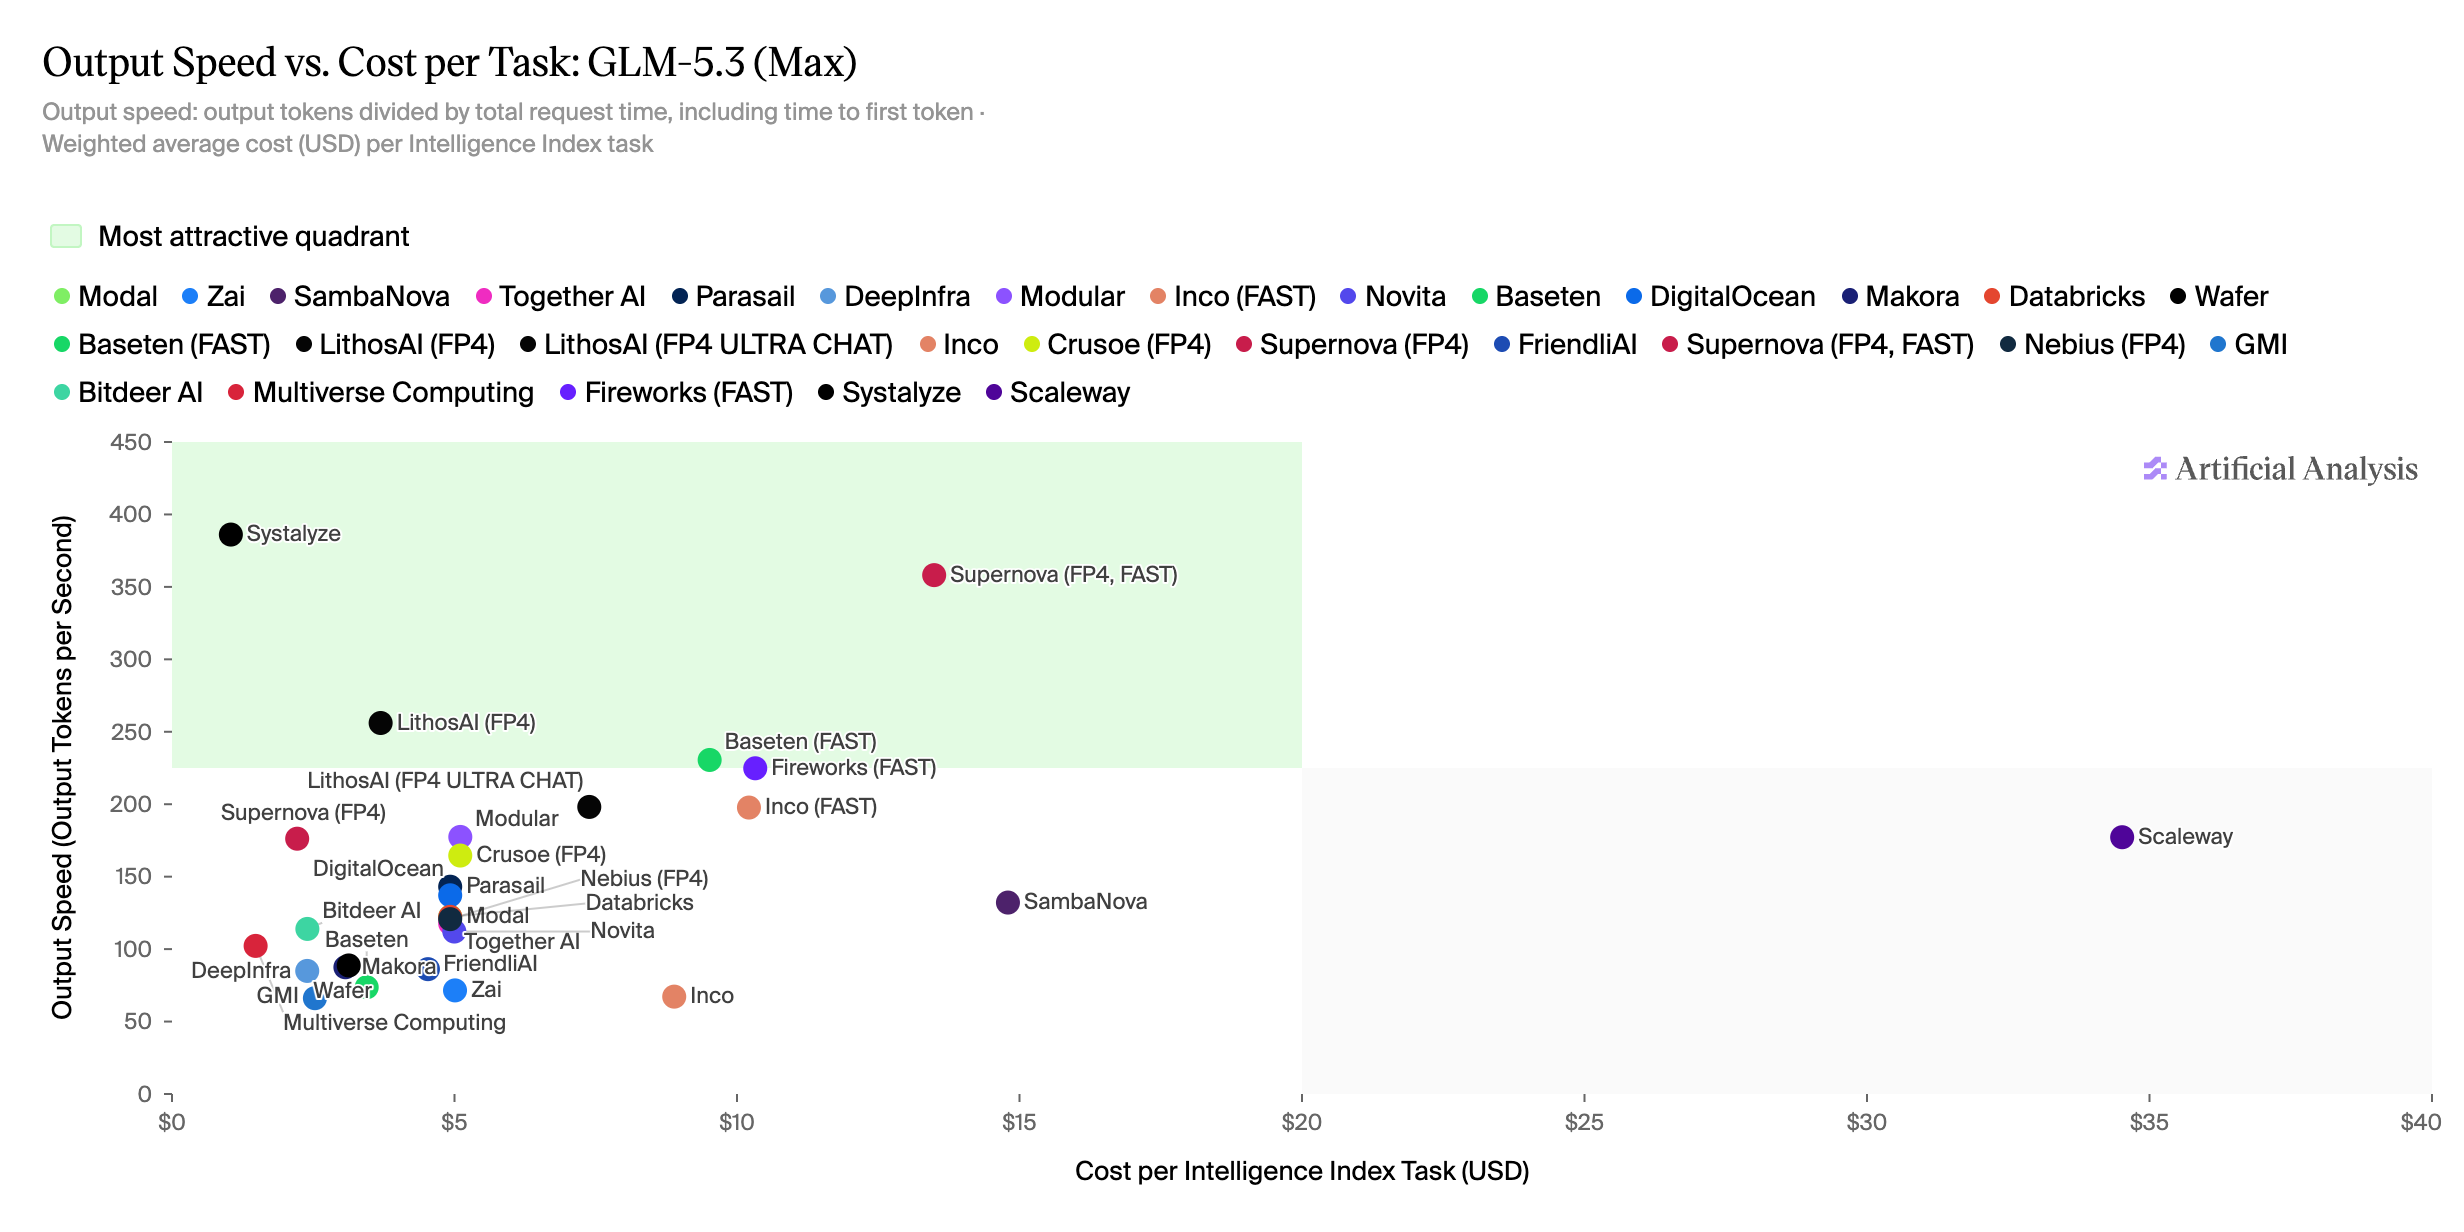
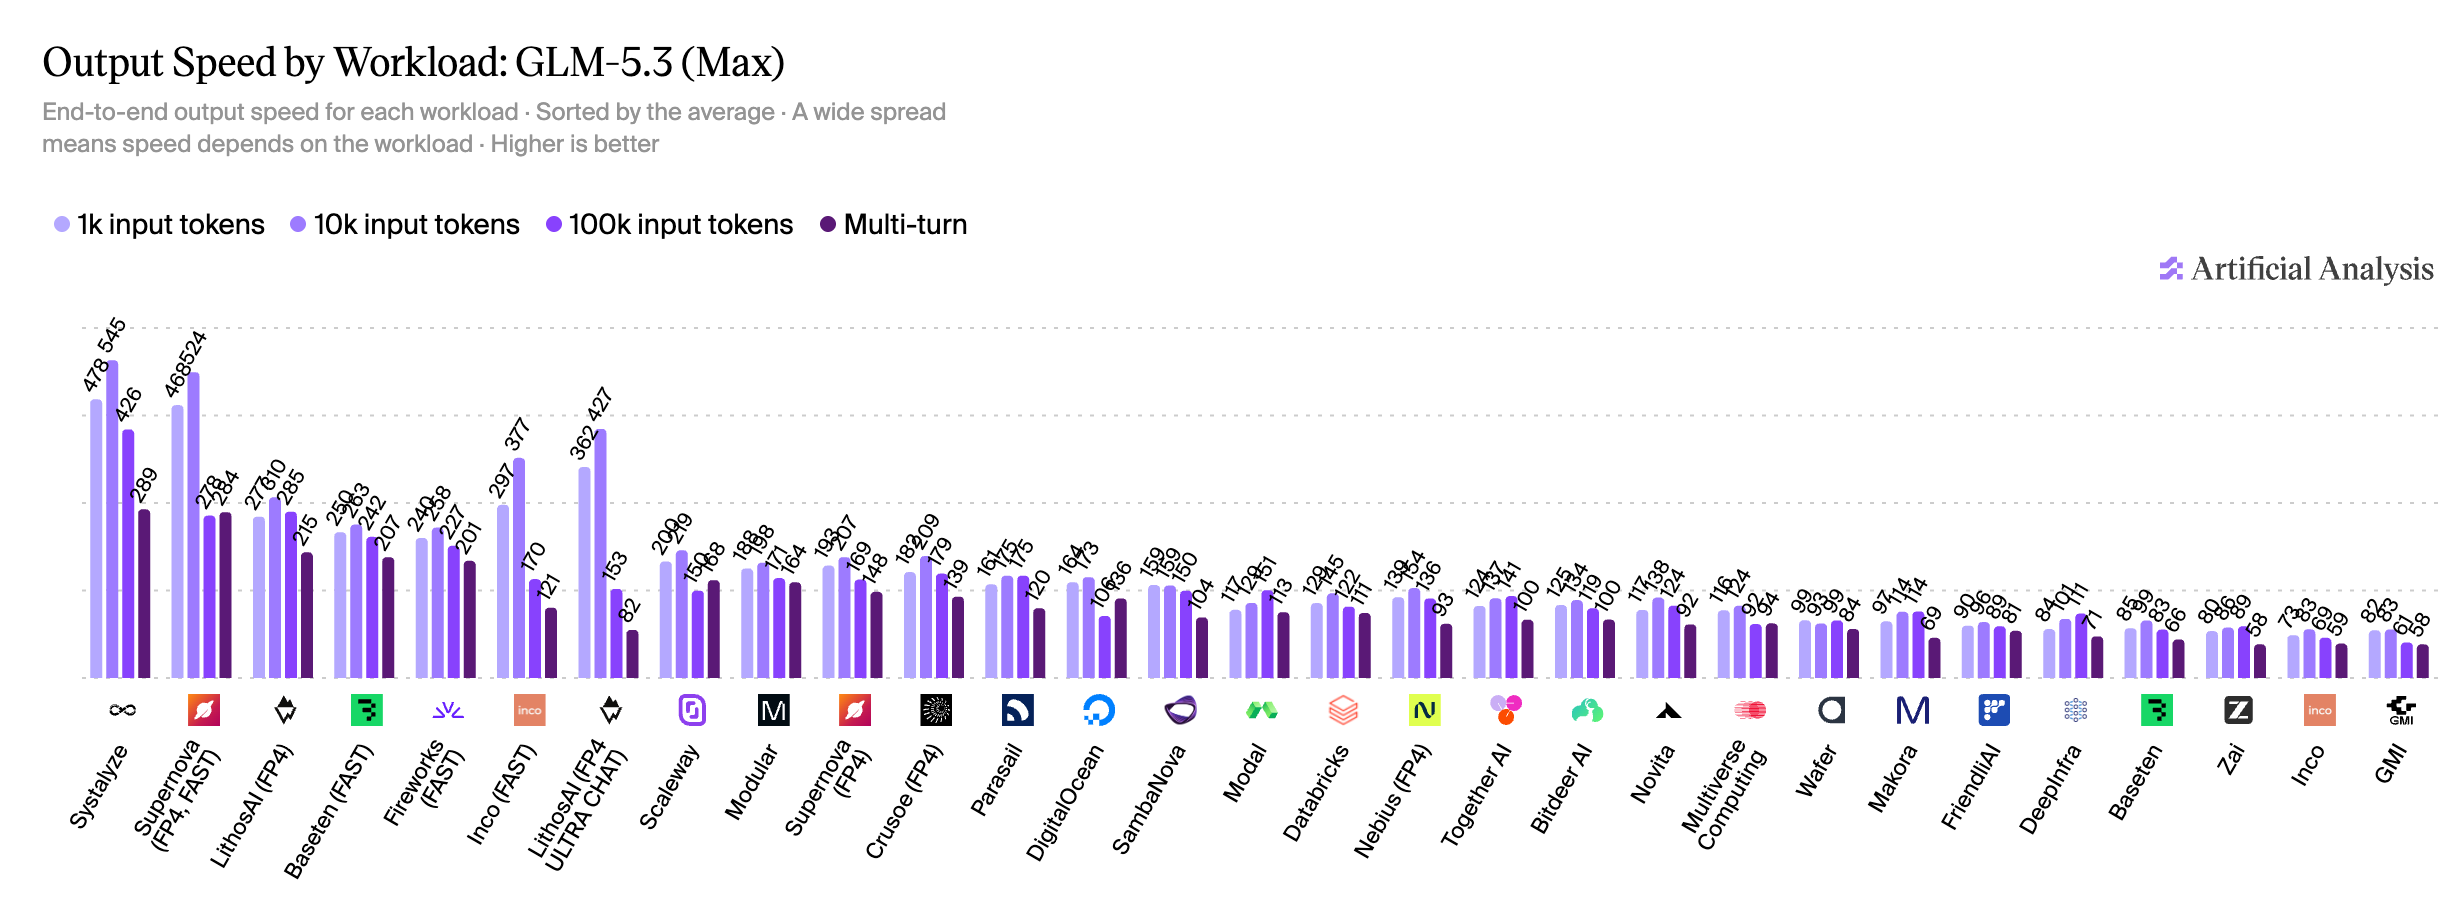
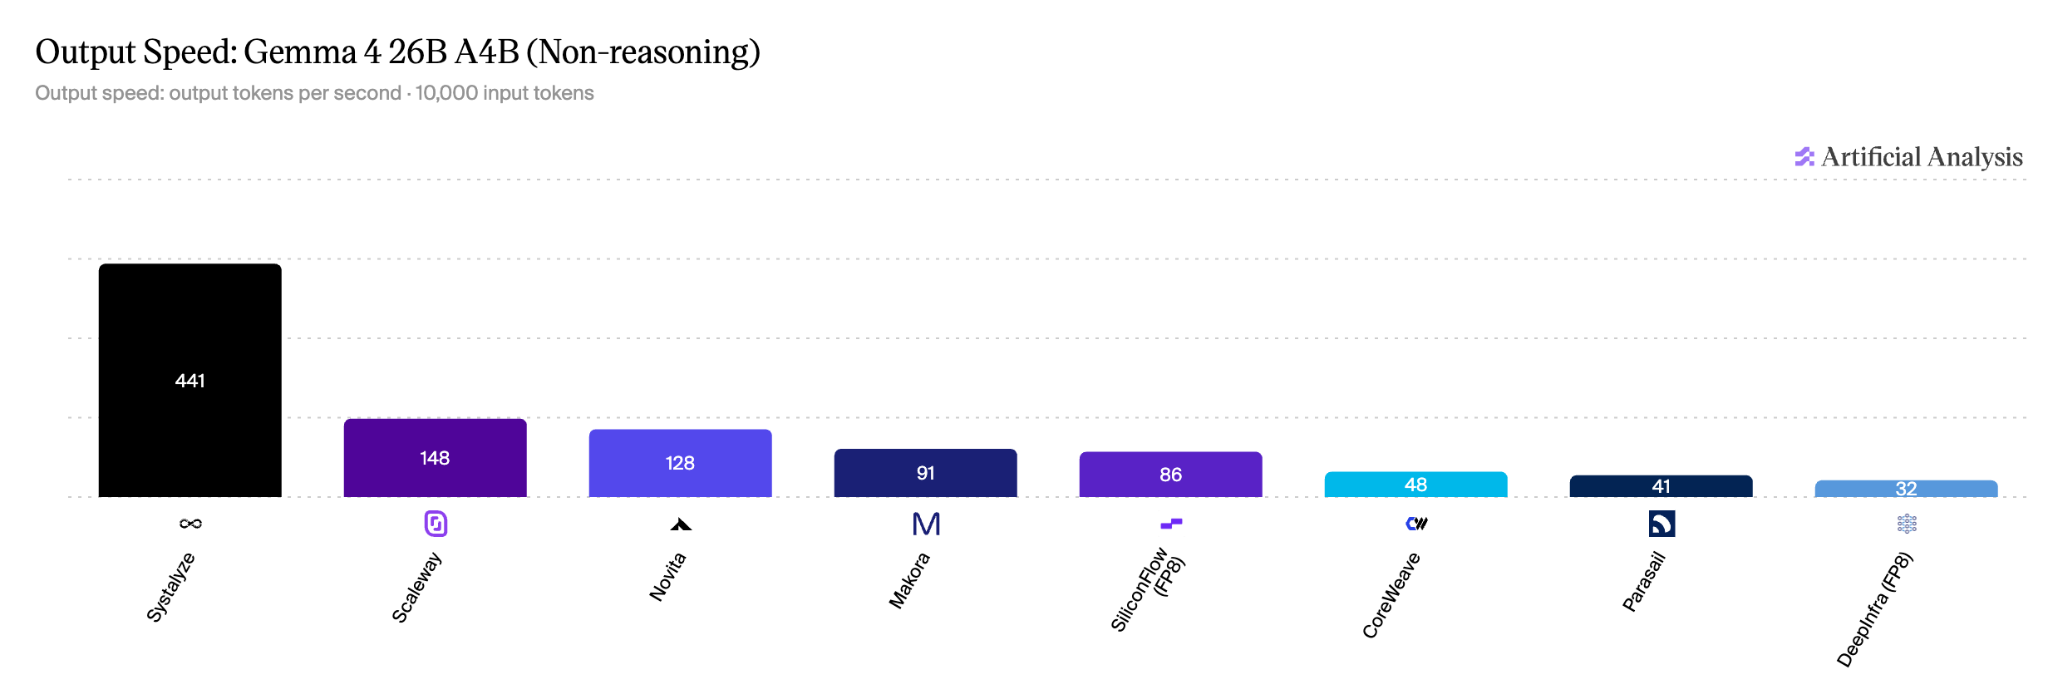
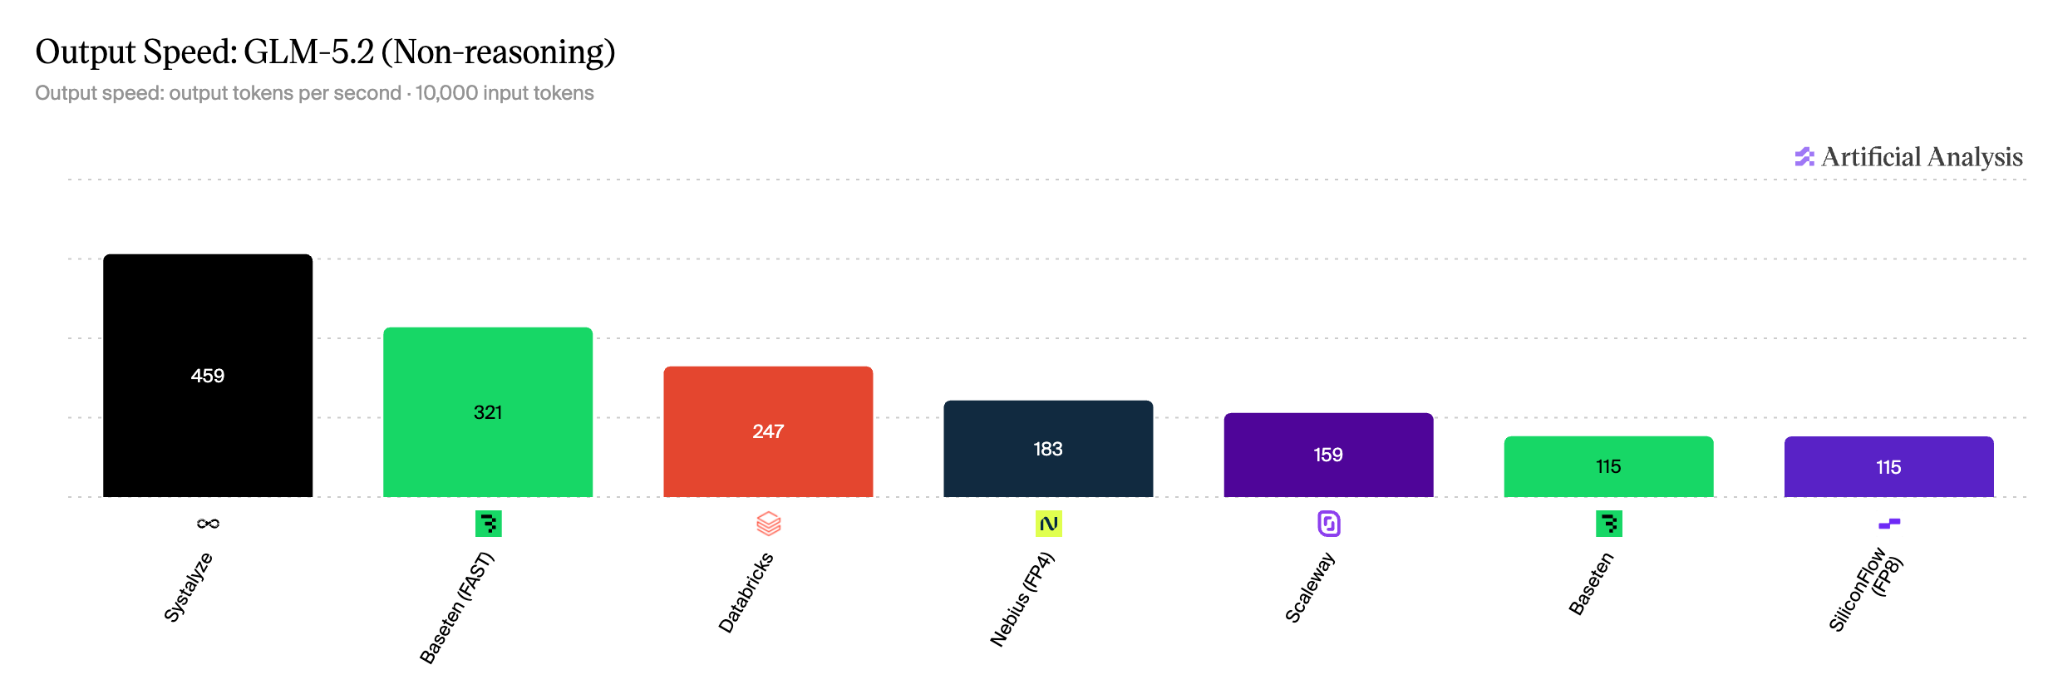
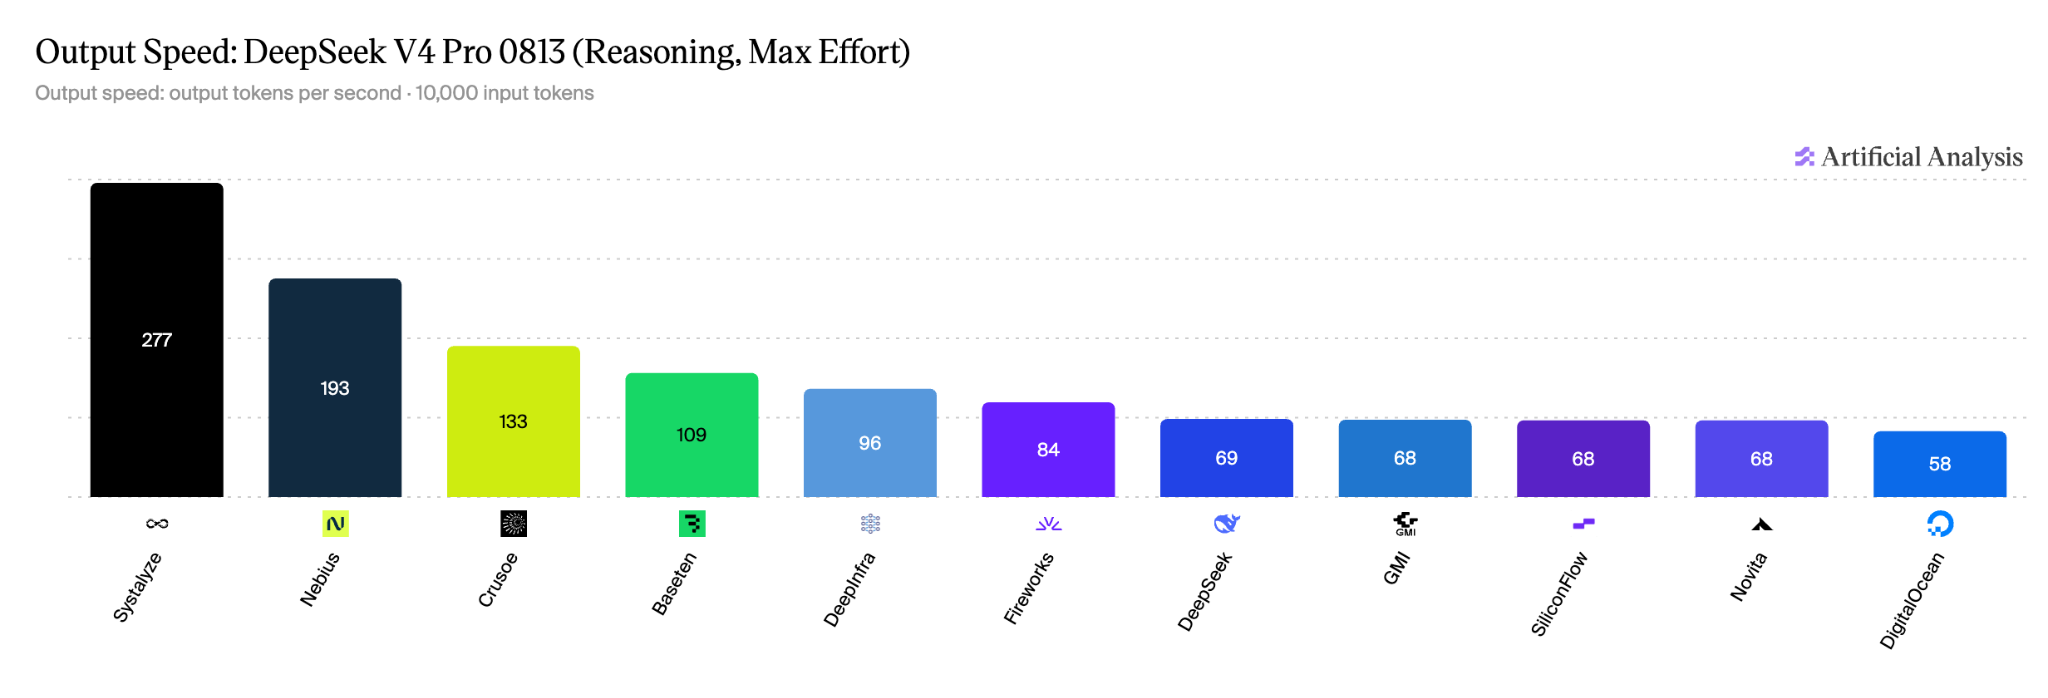
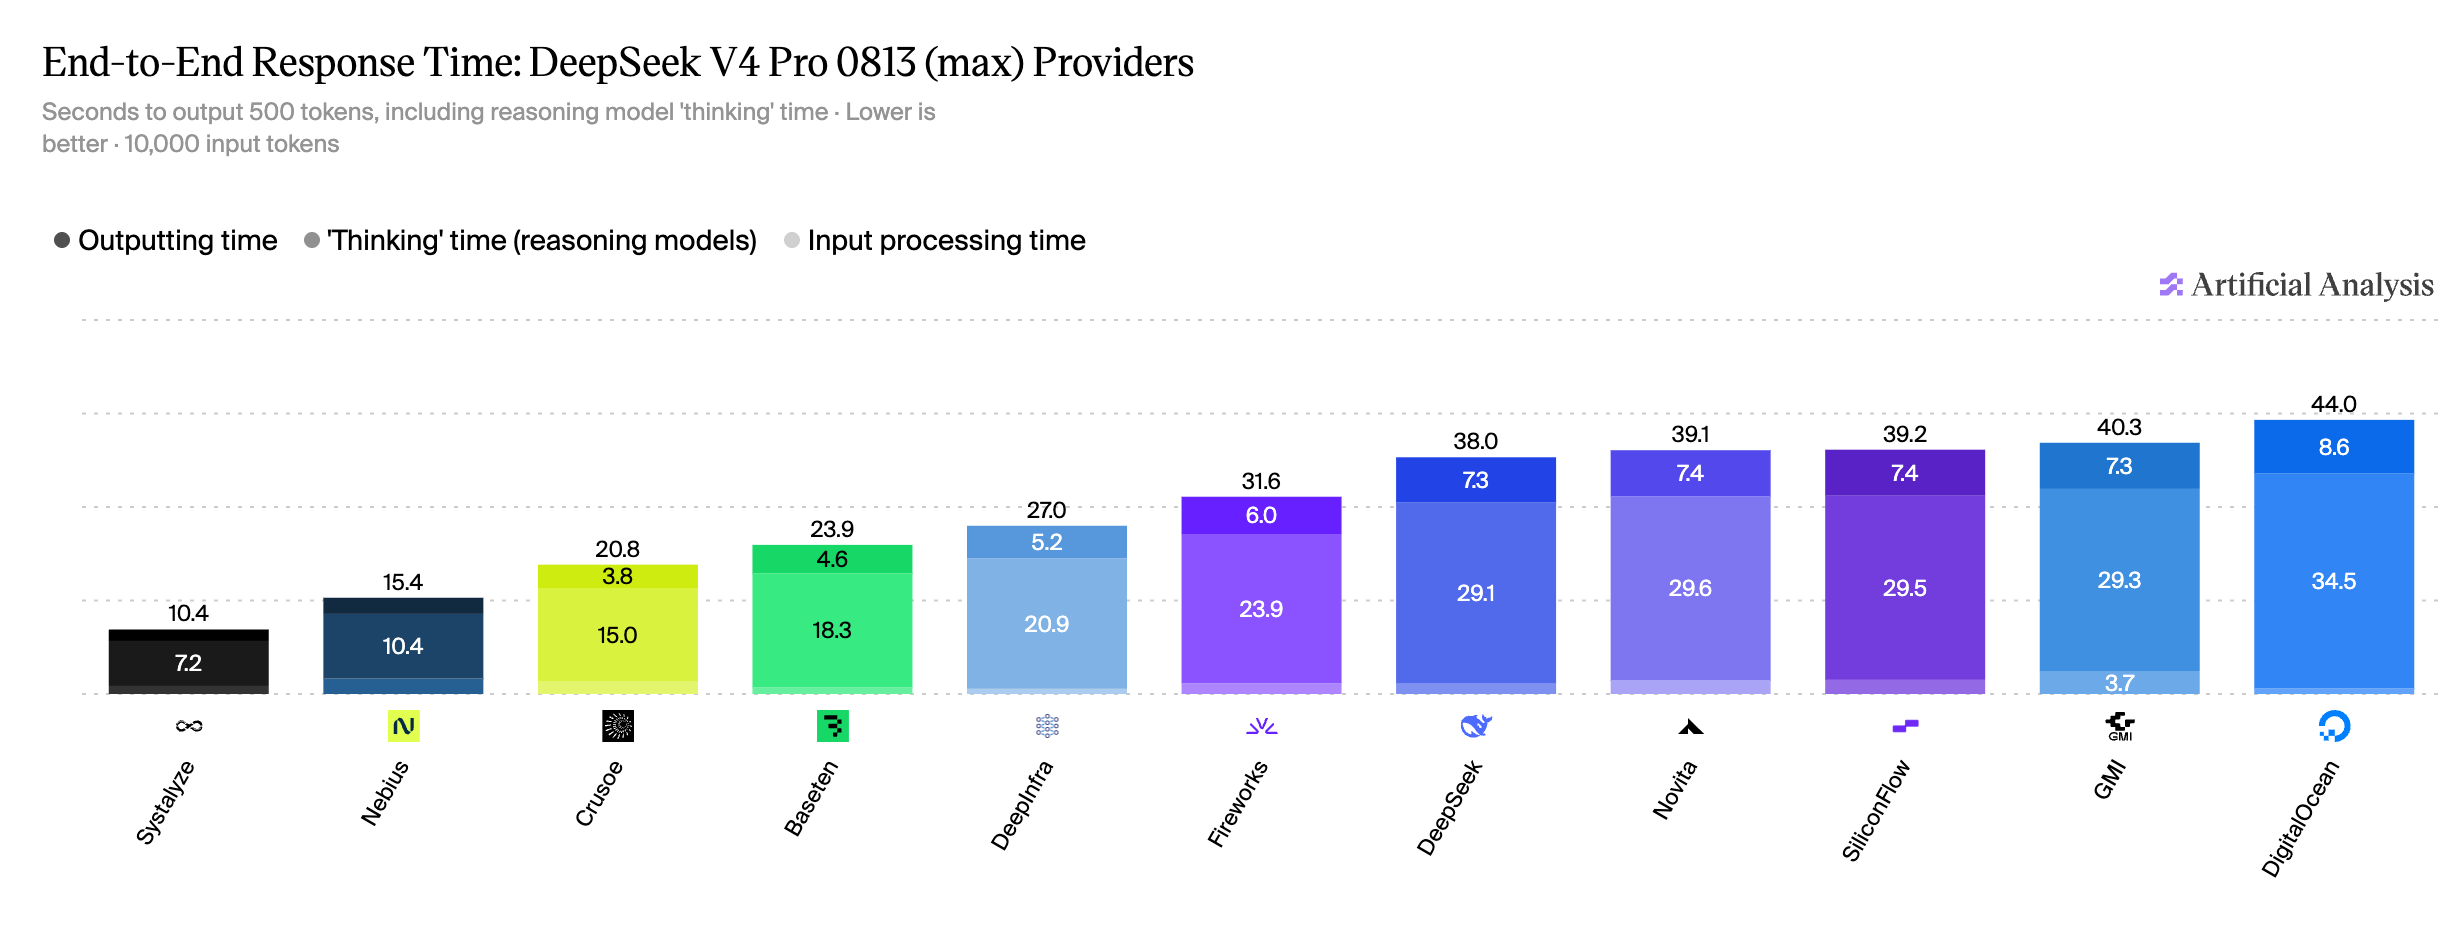
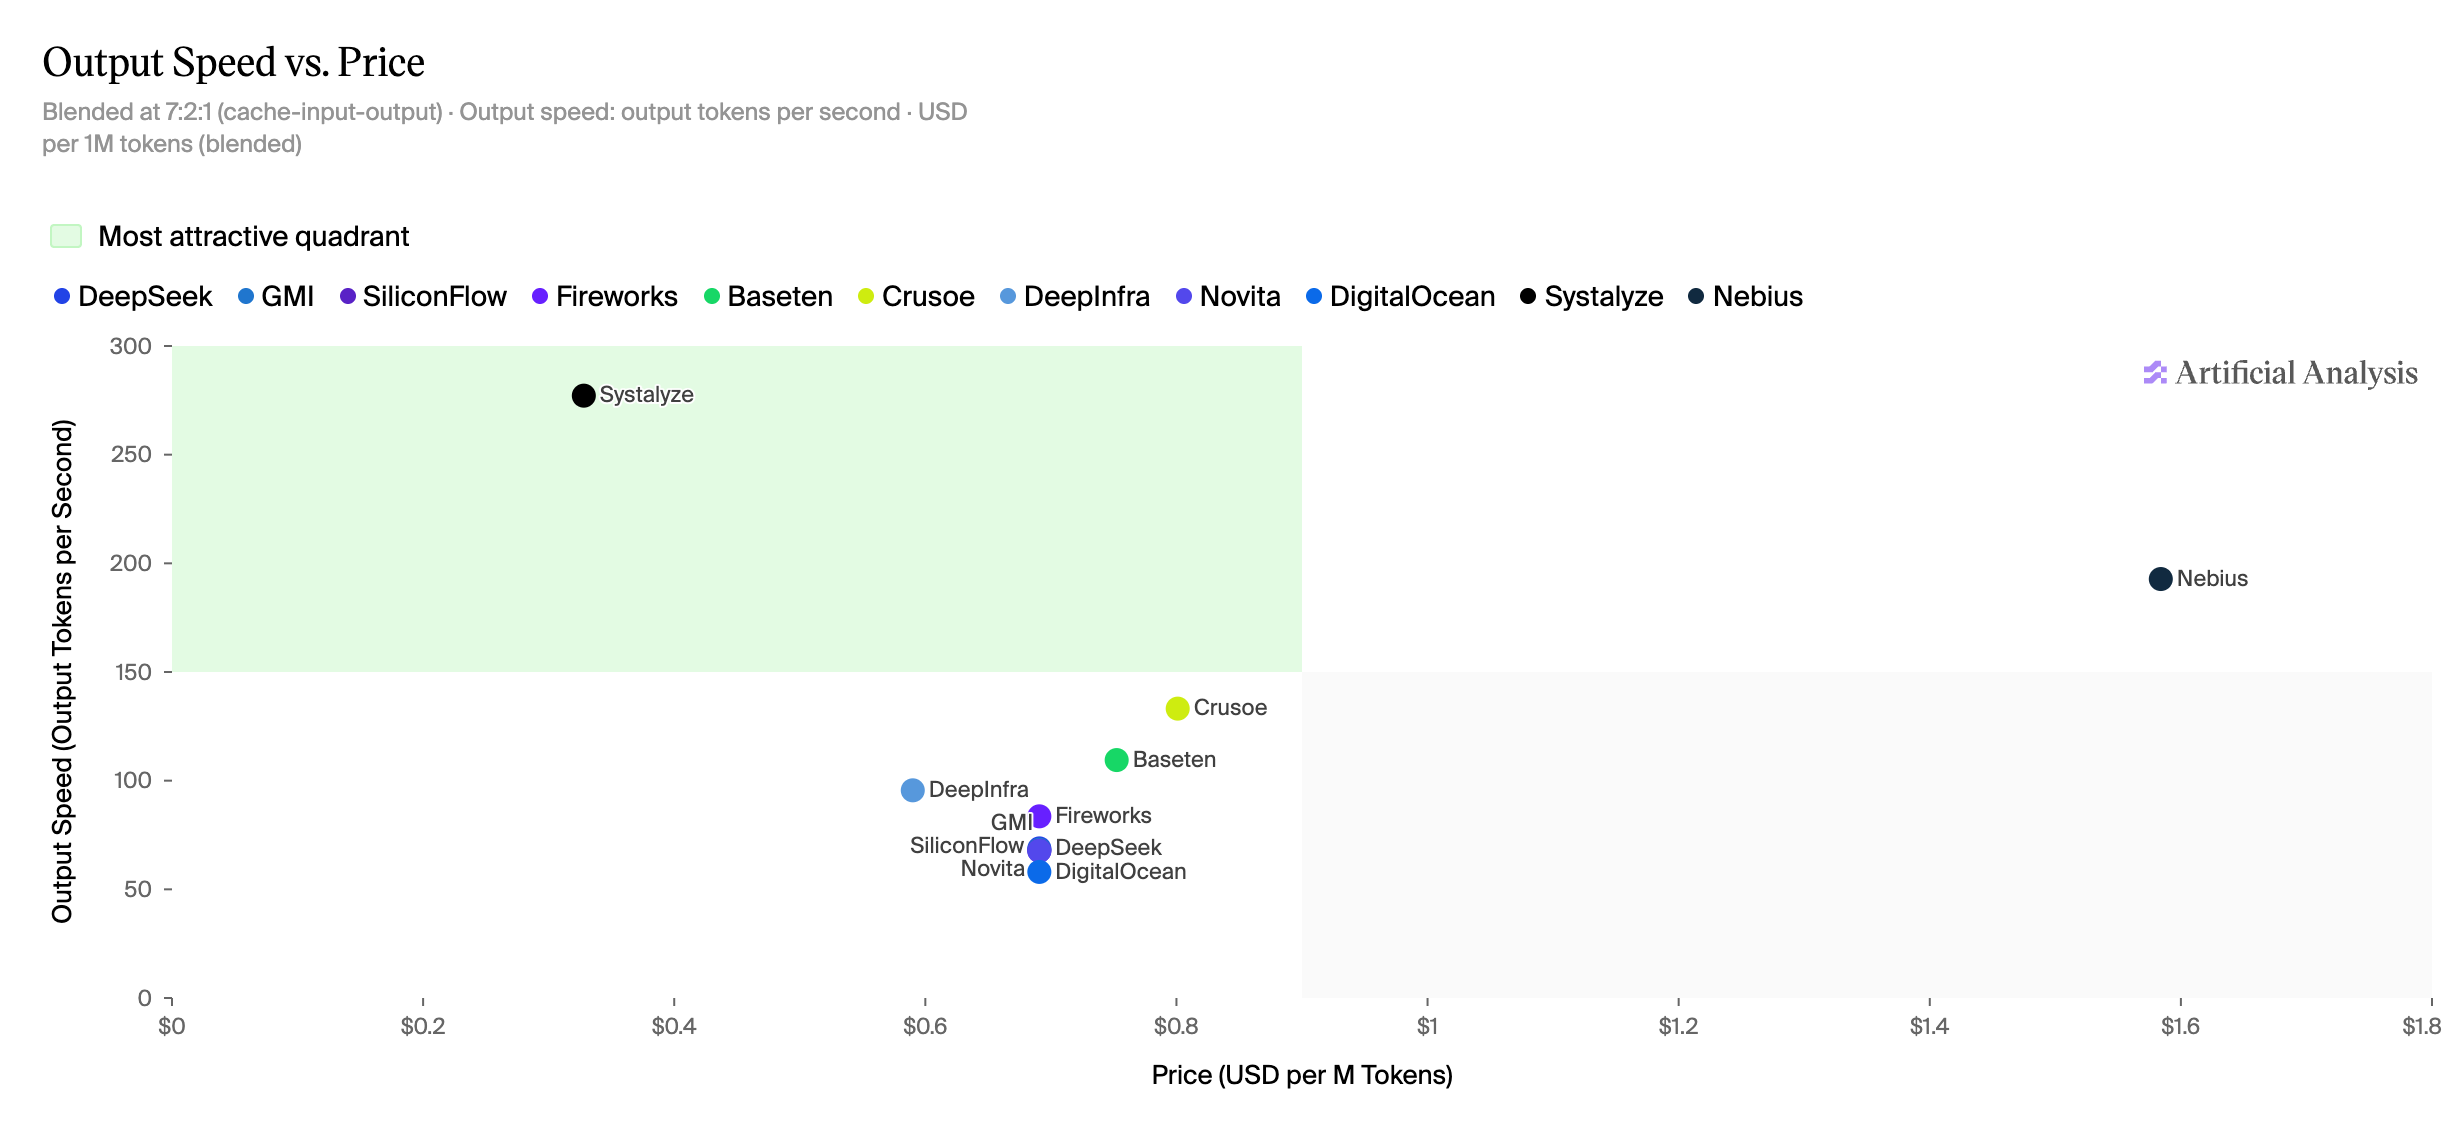
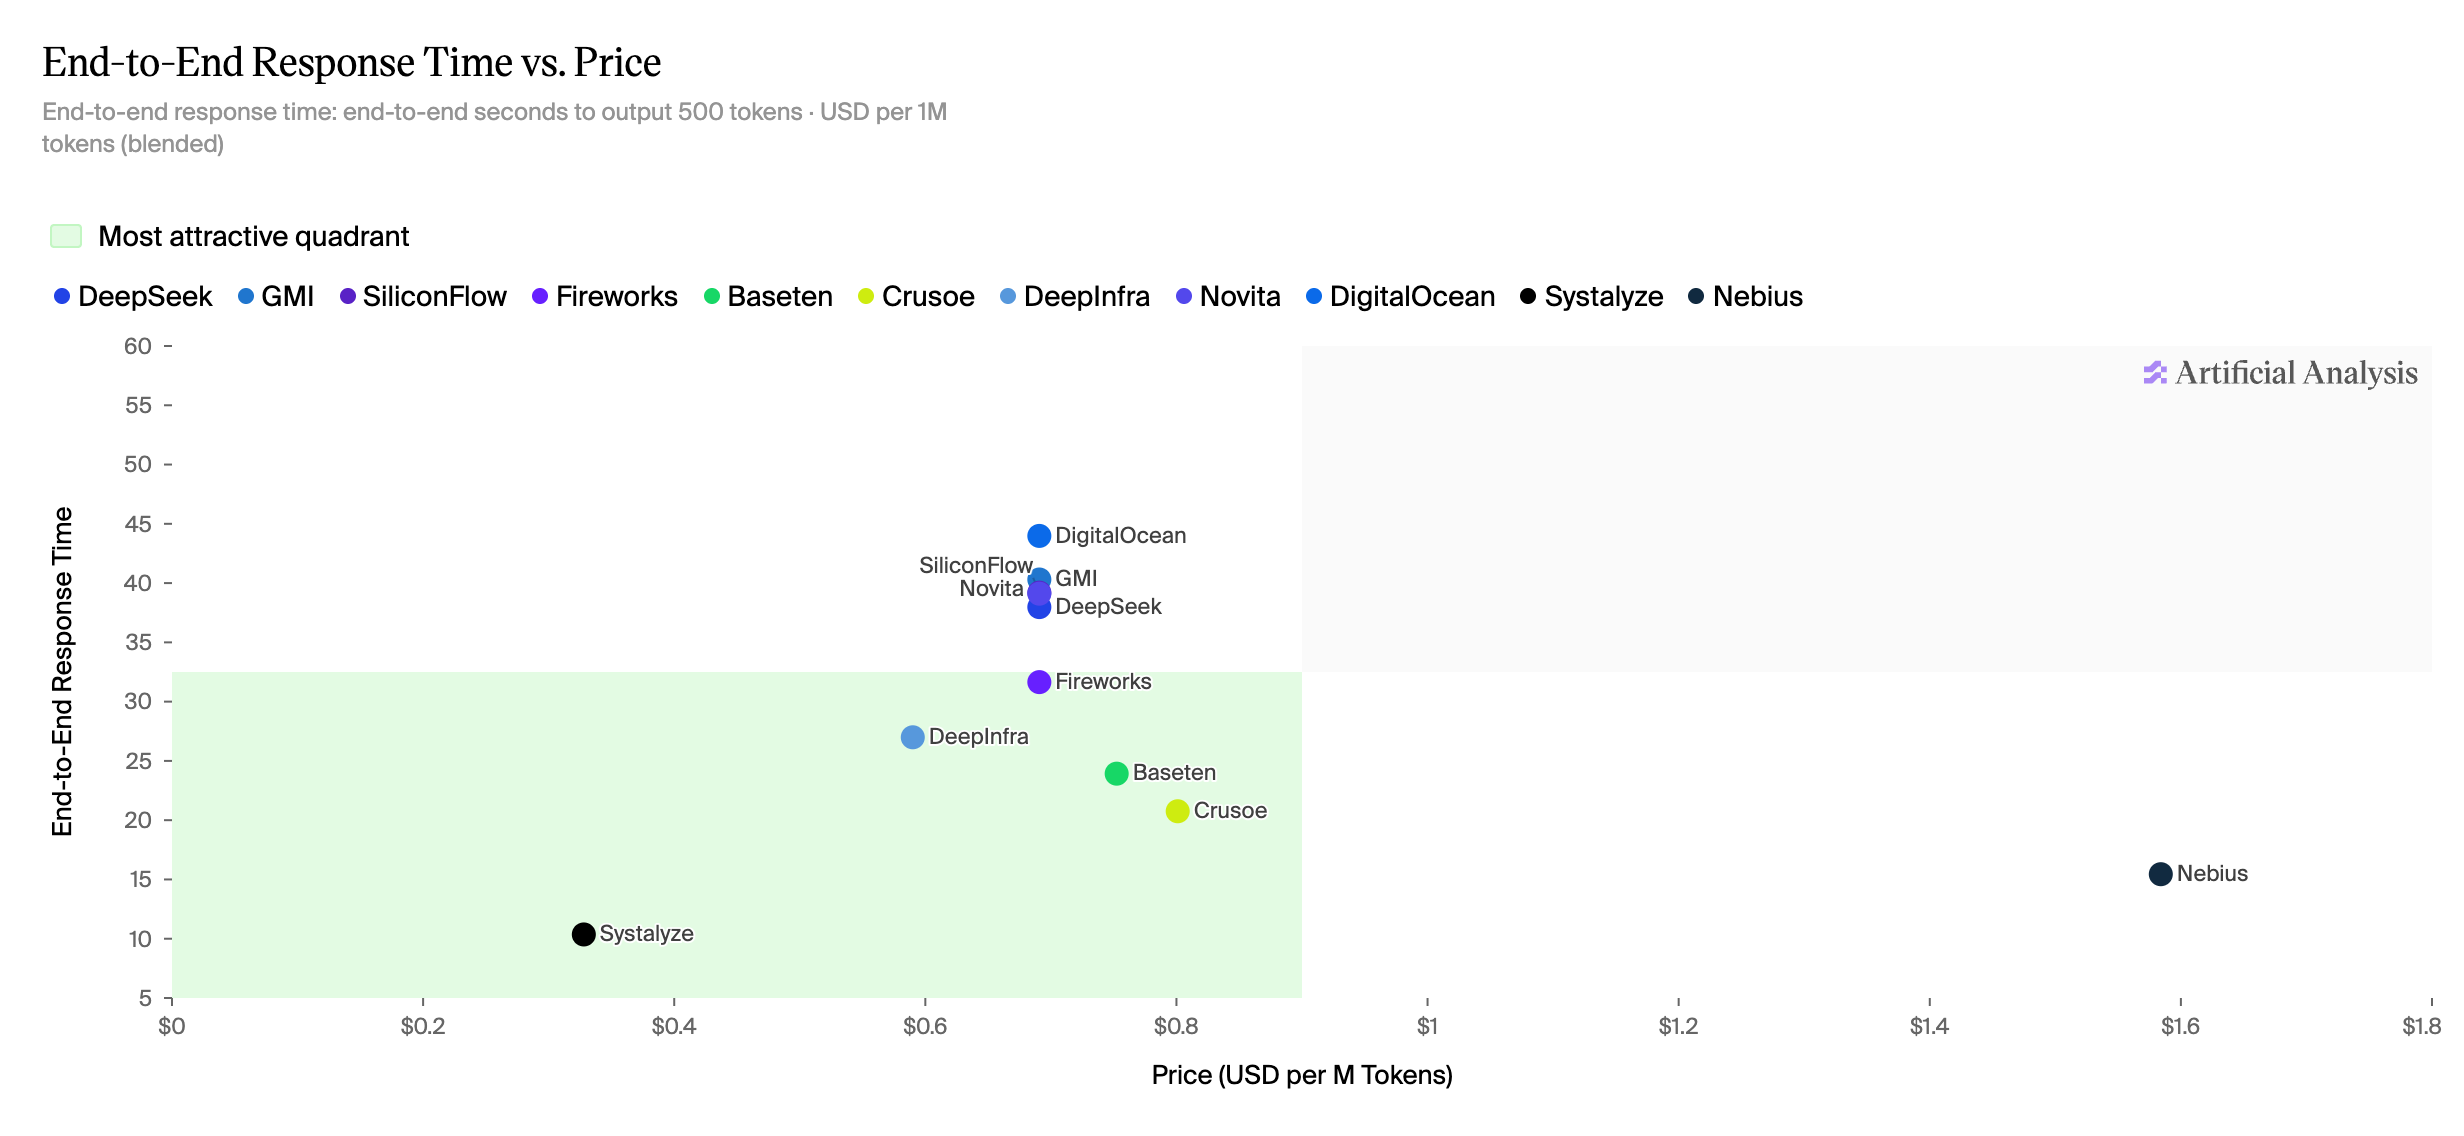
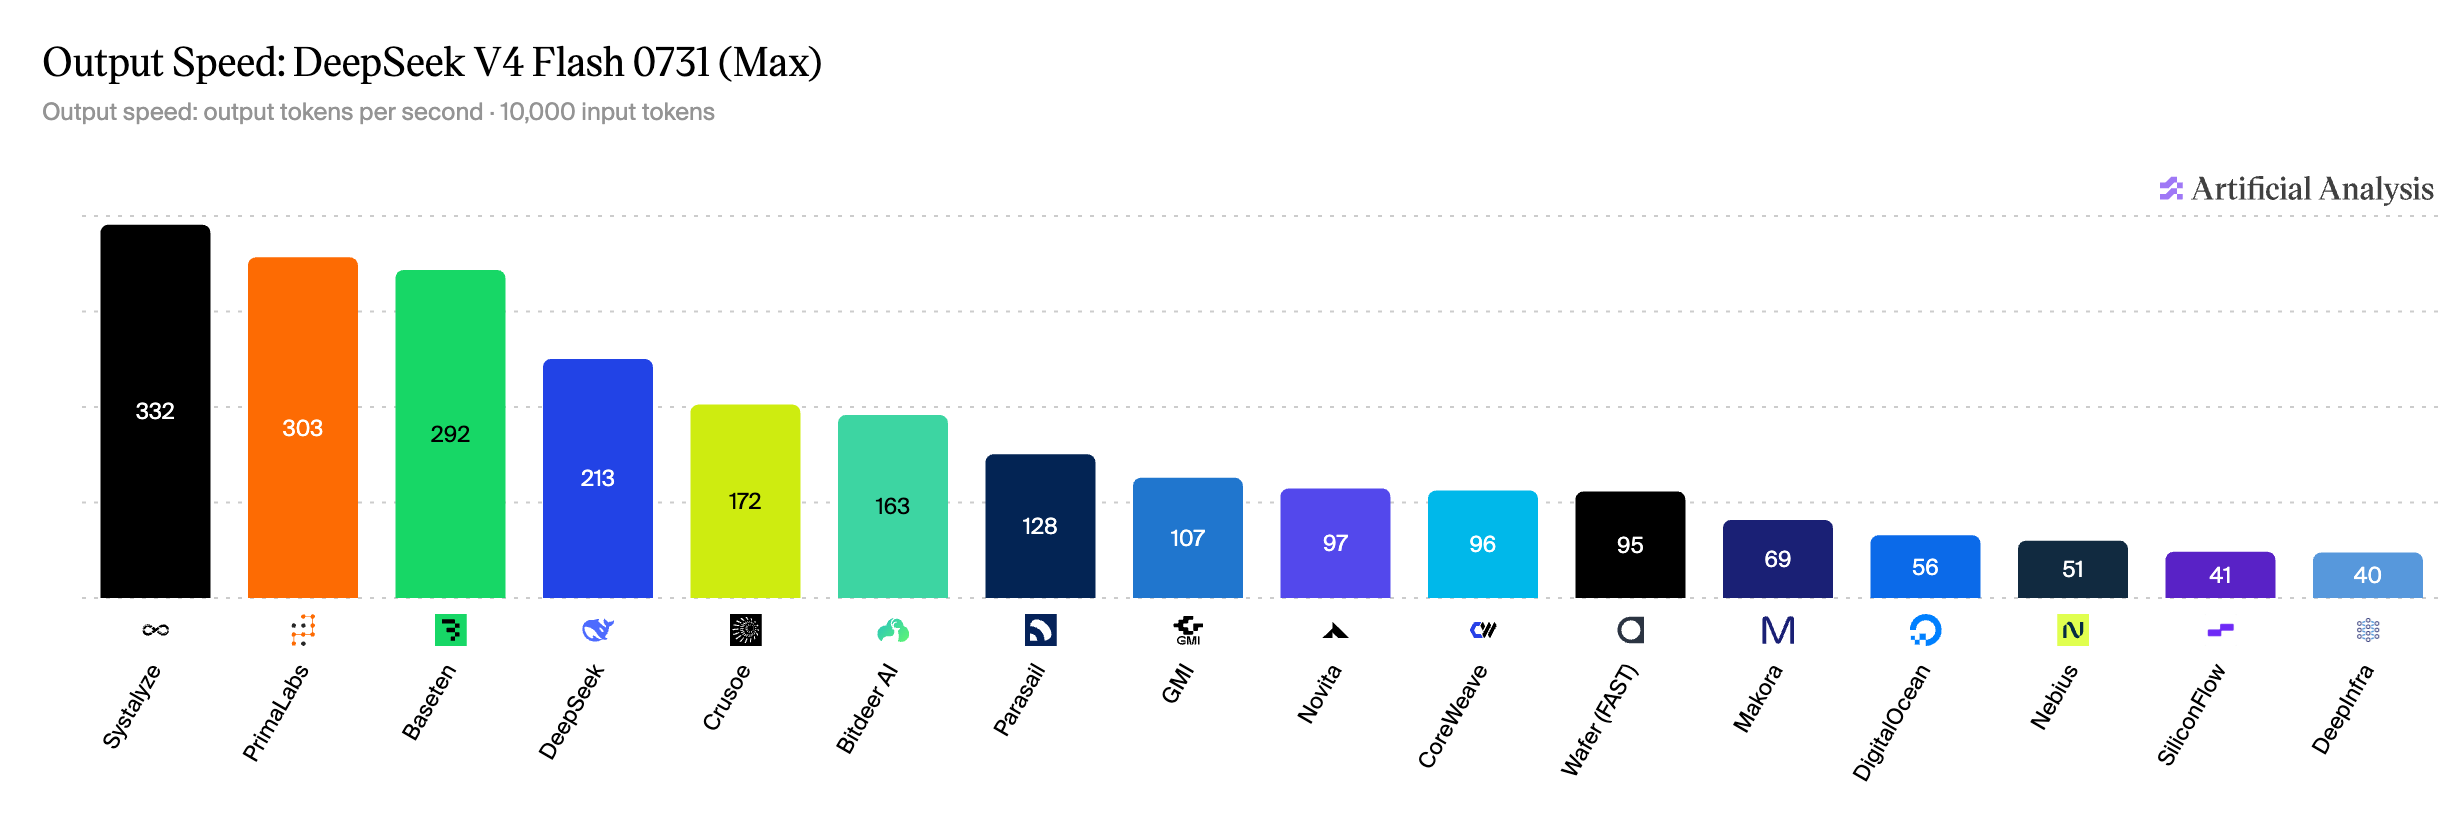
Output speed
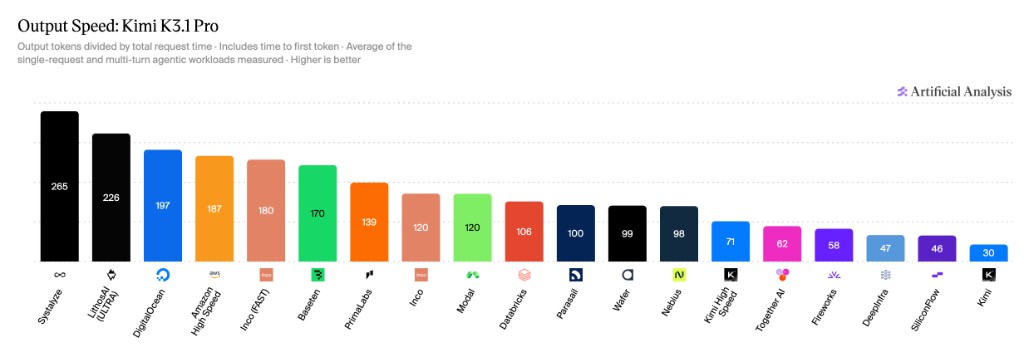
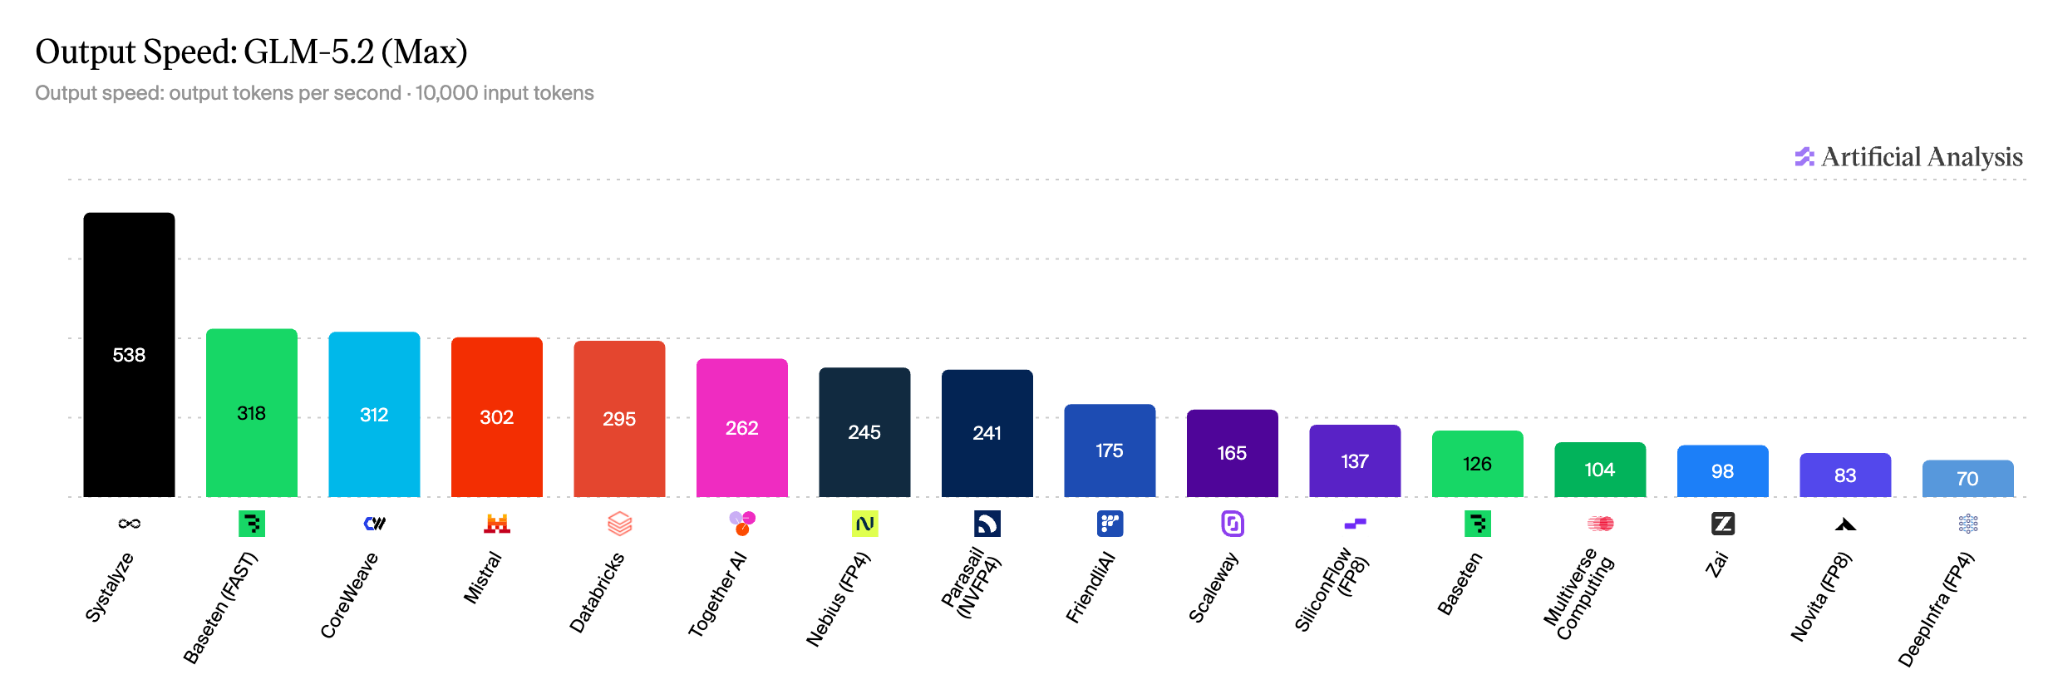
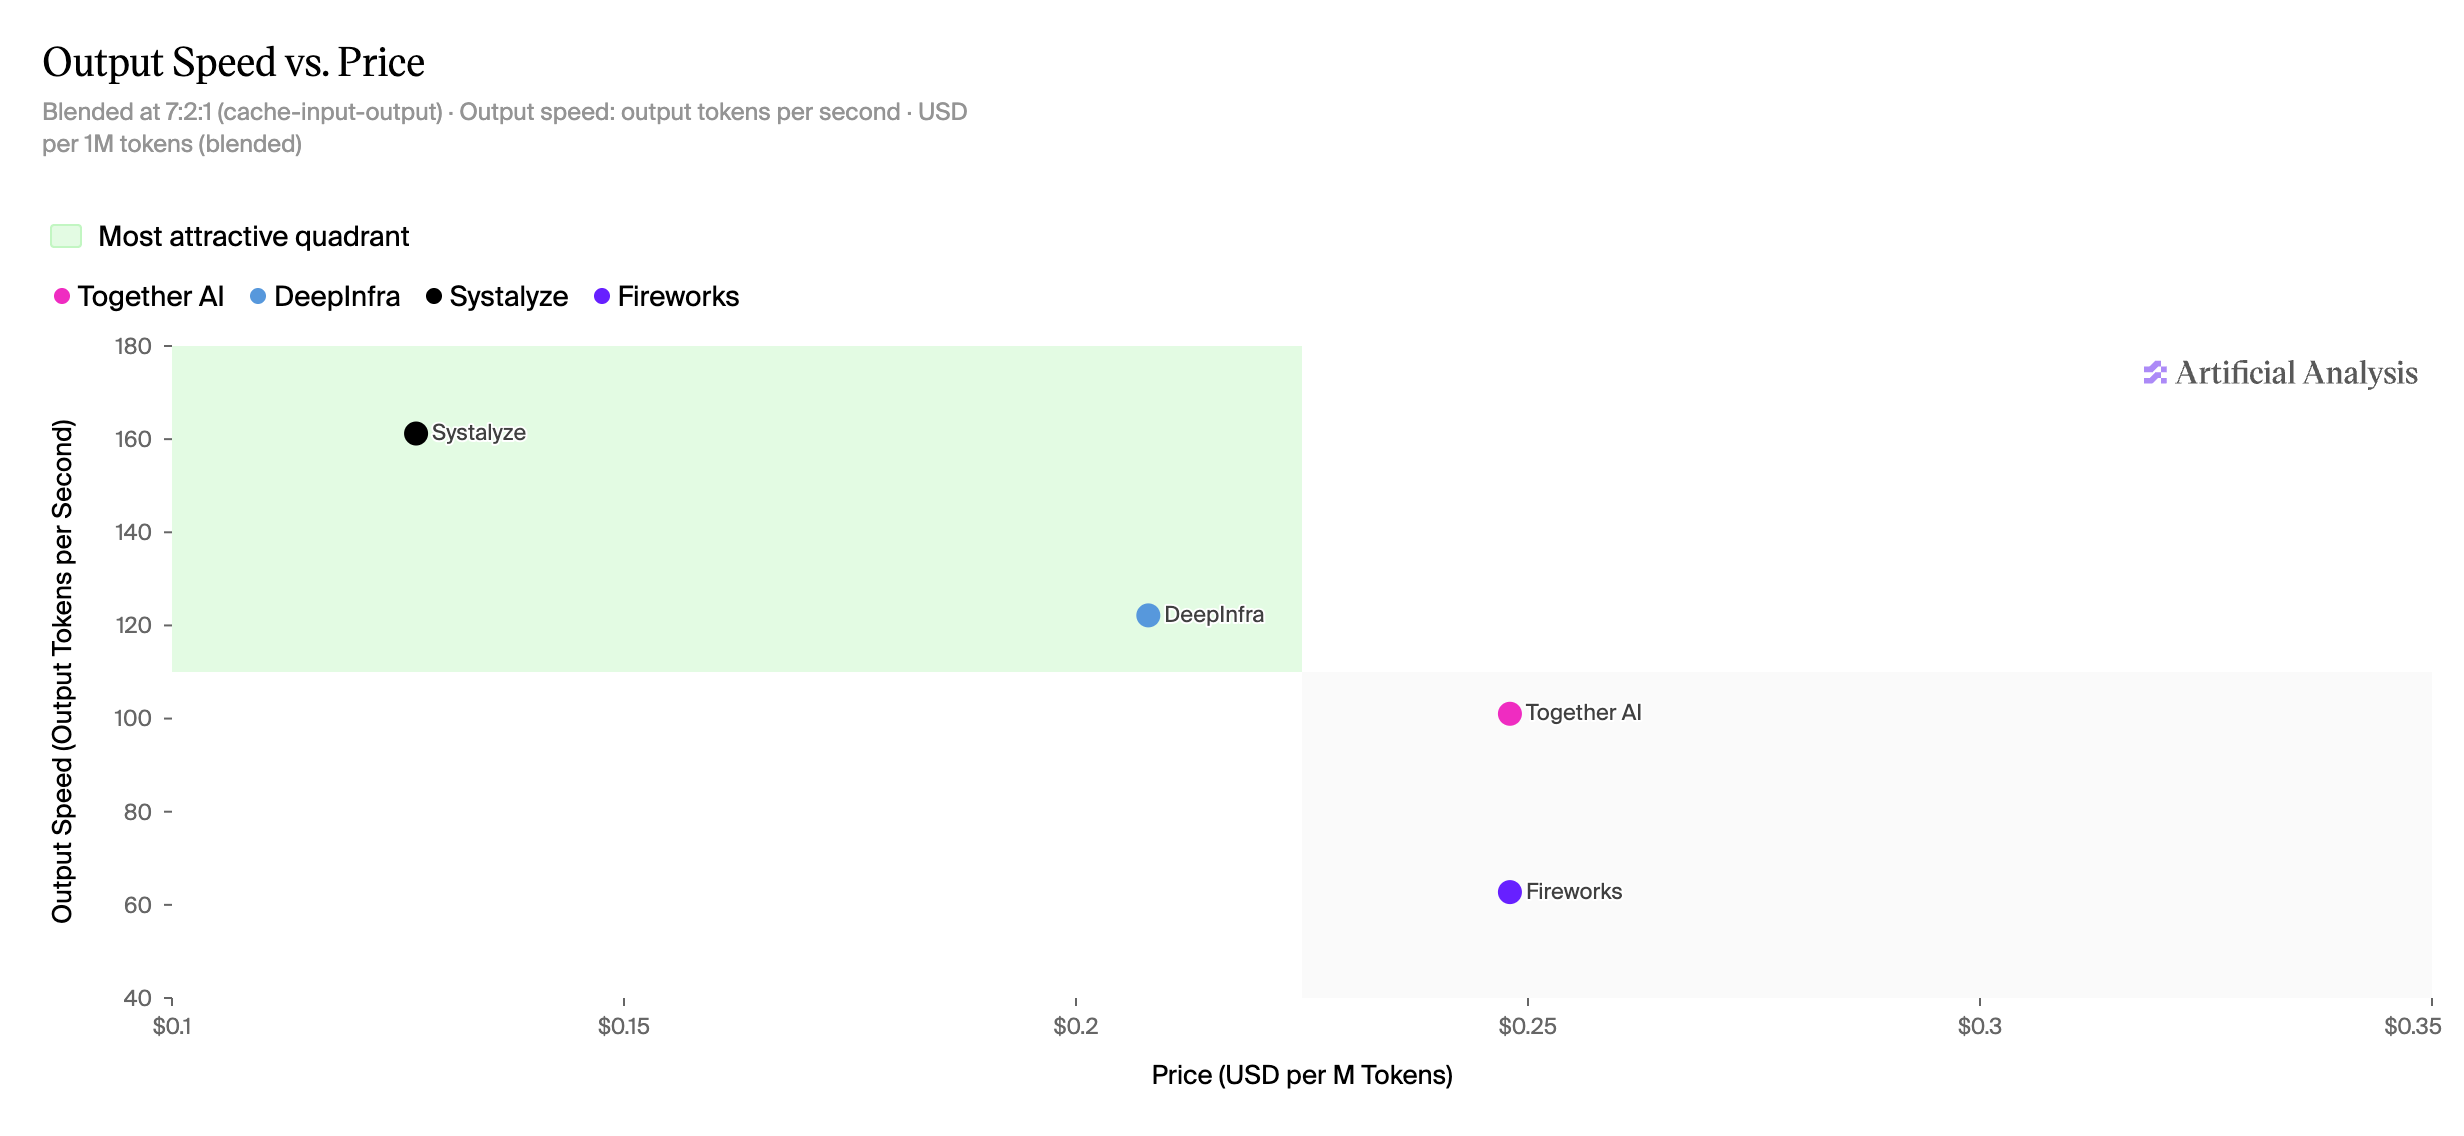
265 tokens per second
#1 of 19 endpoints on output speed. 8.8× Kimi's own API.
Best gain 8.8×
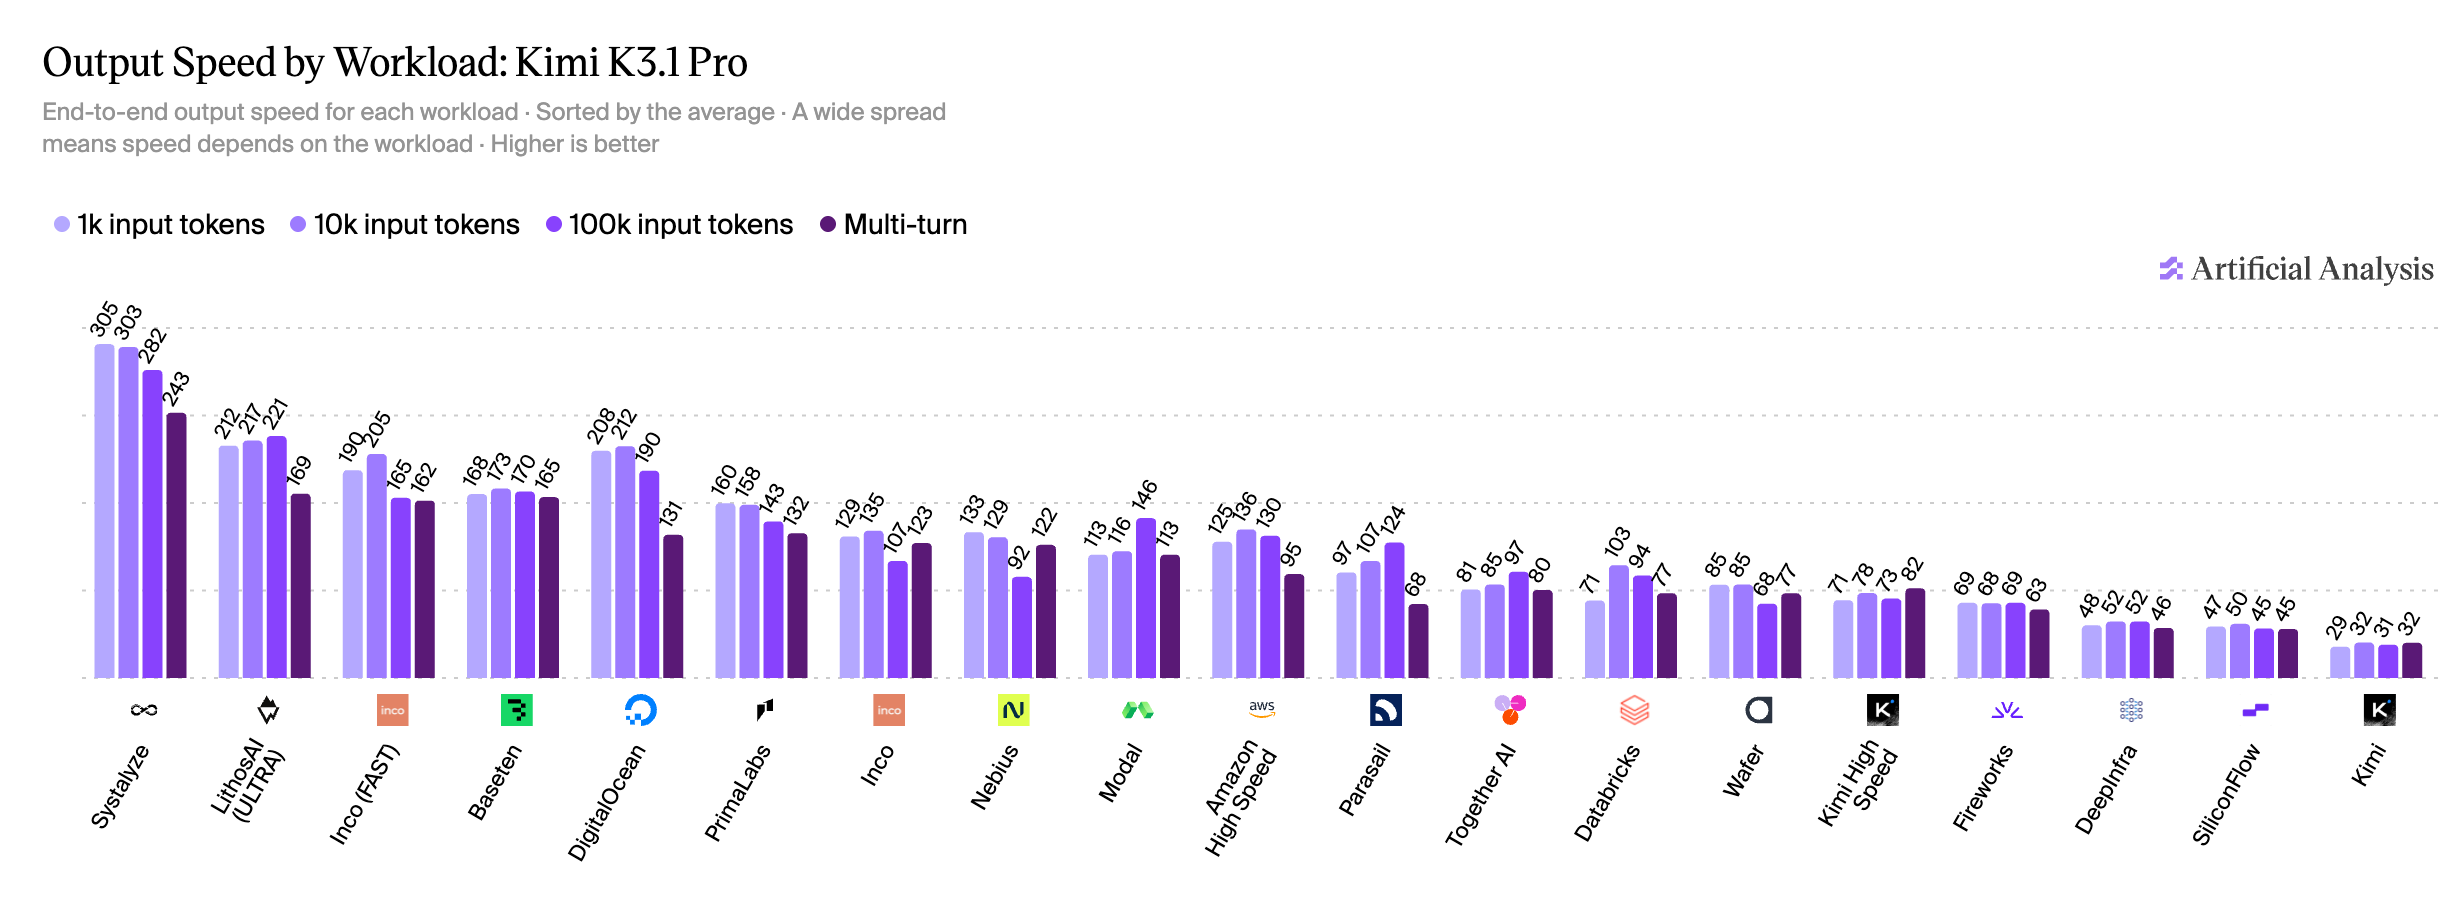
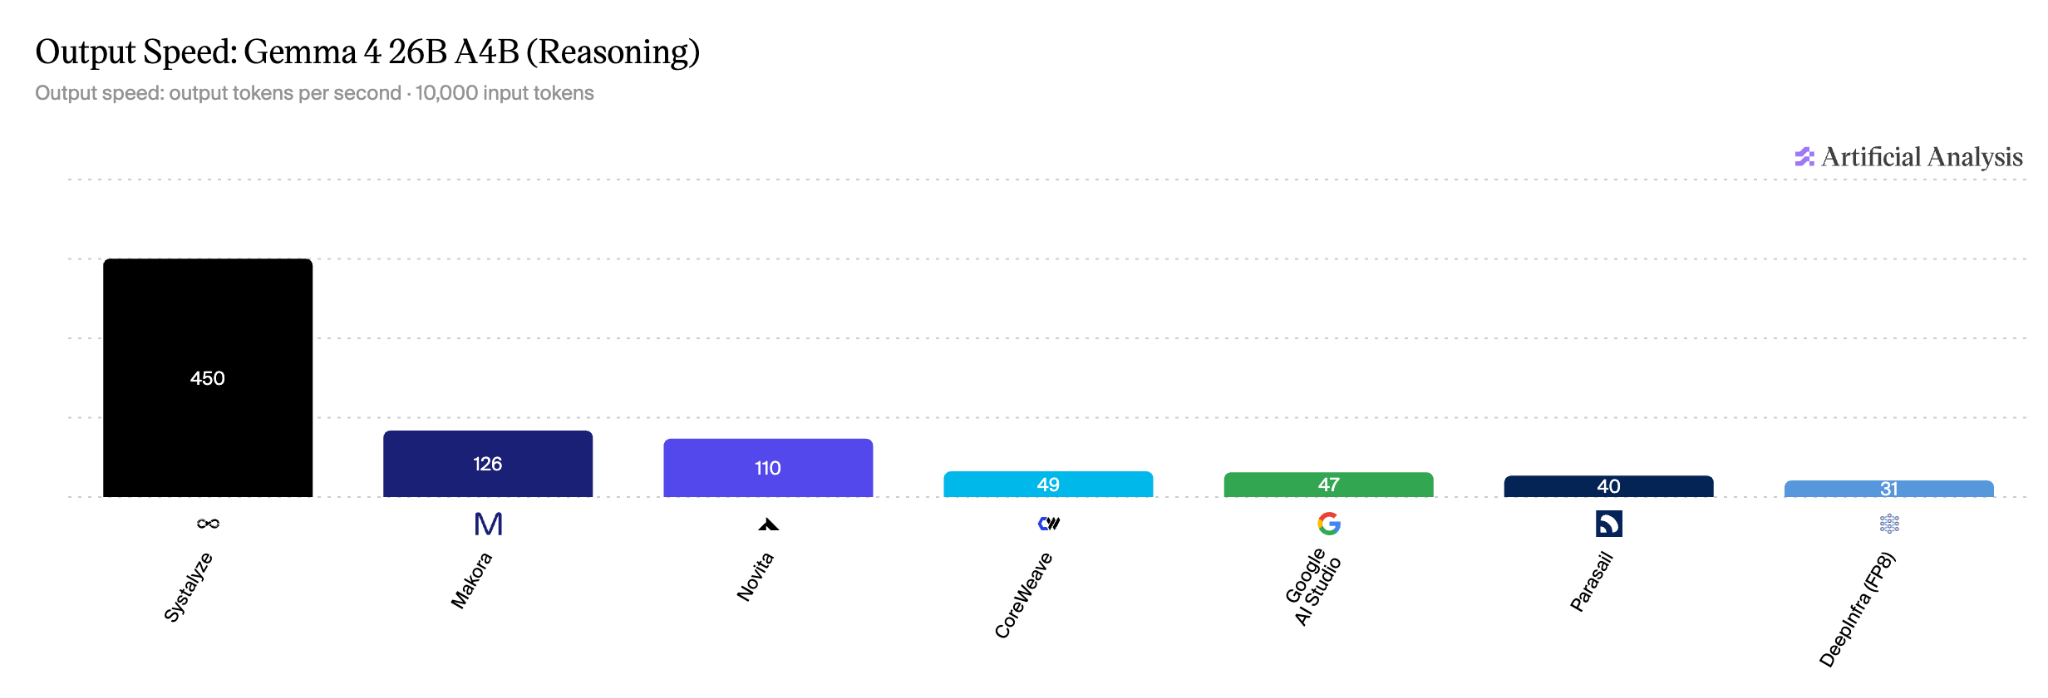
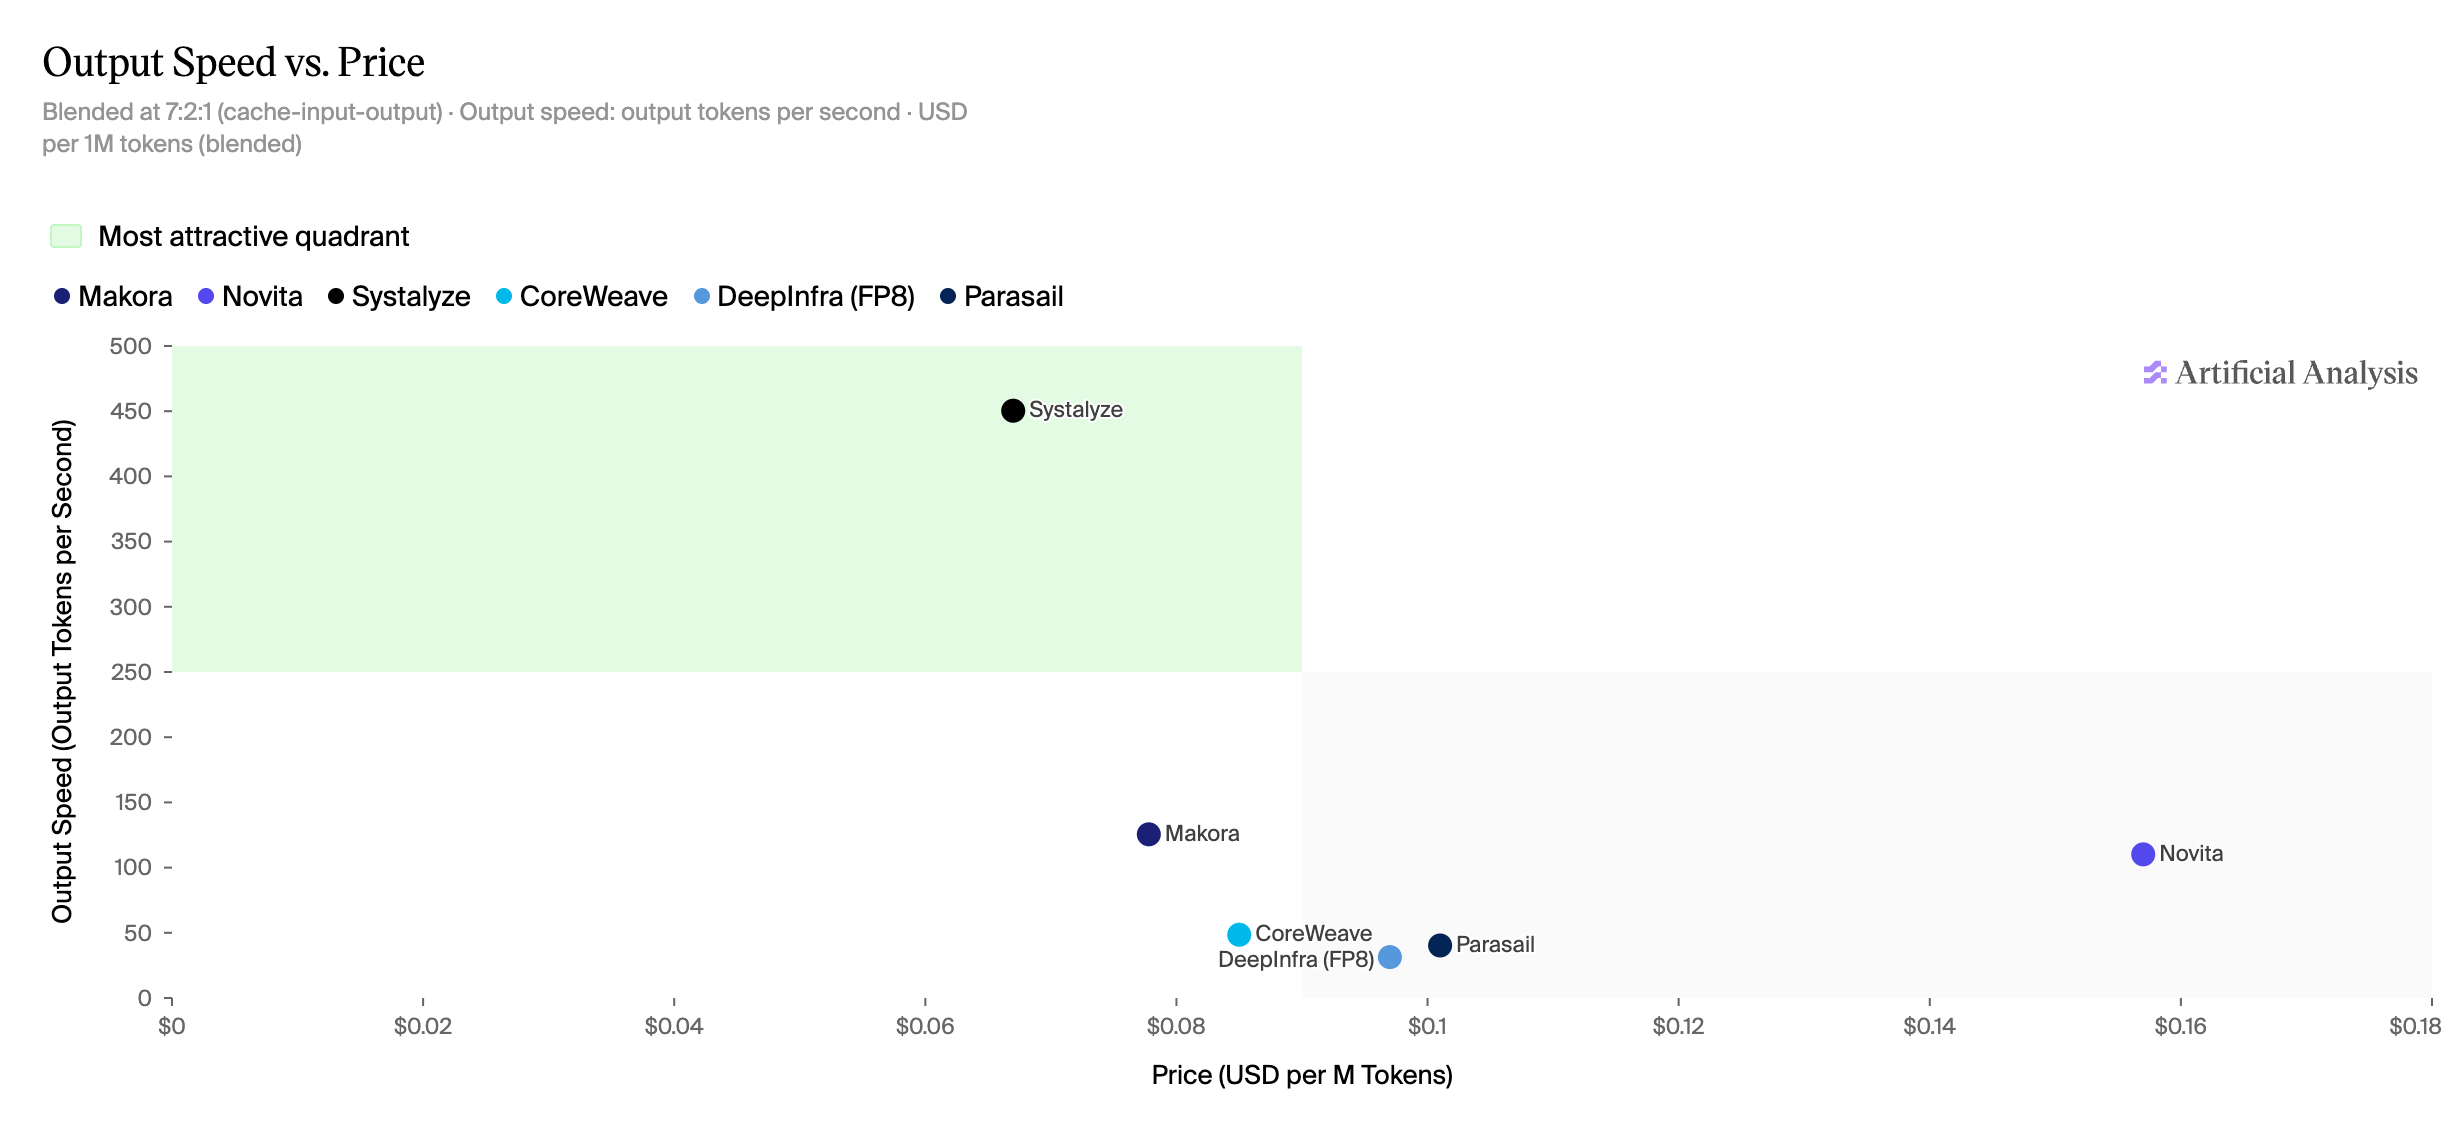
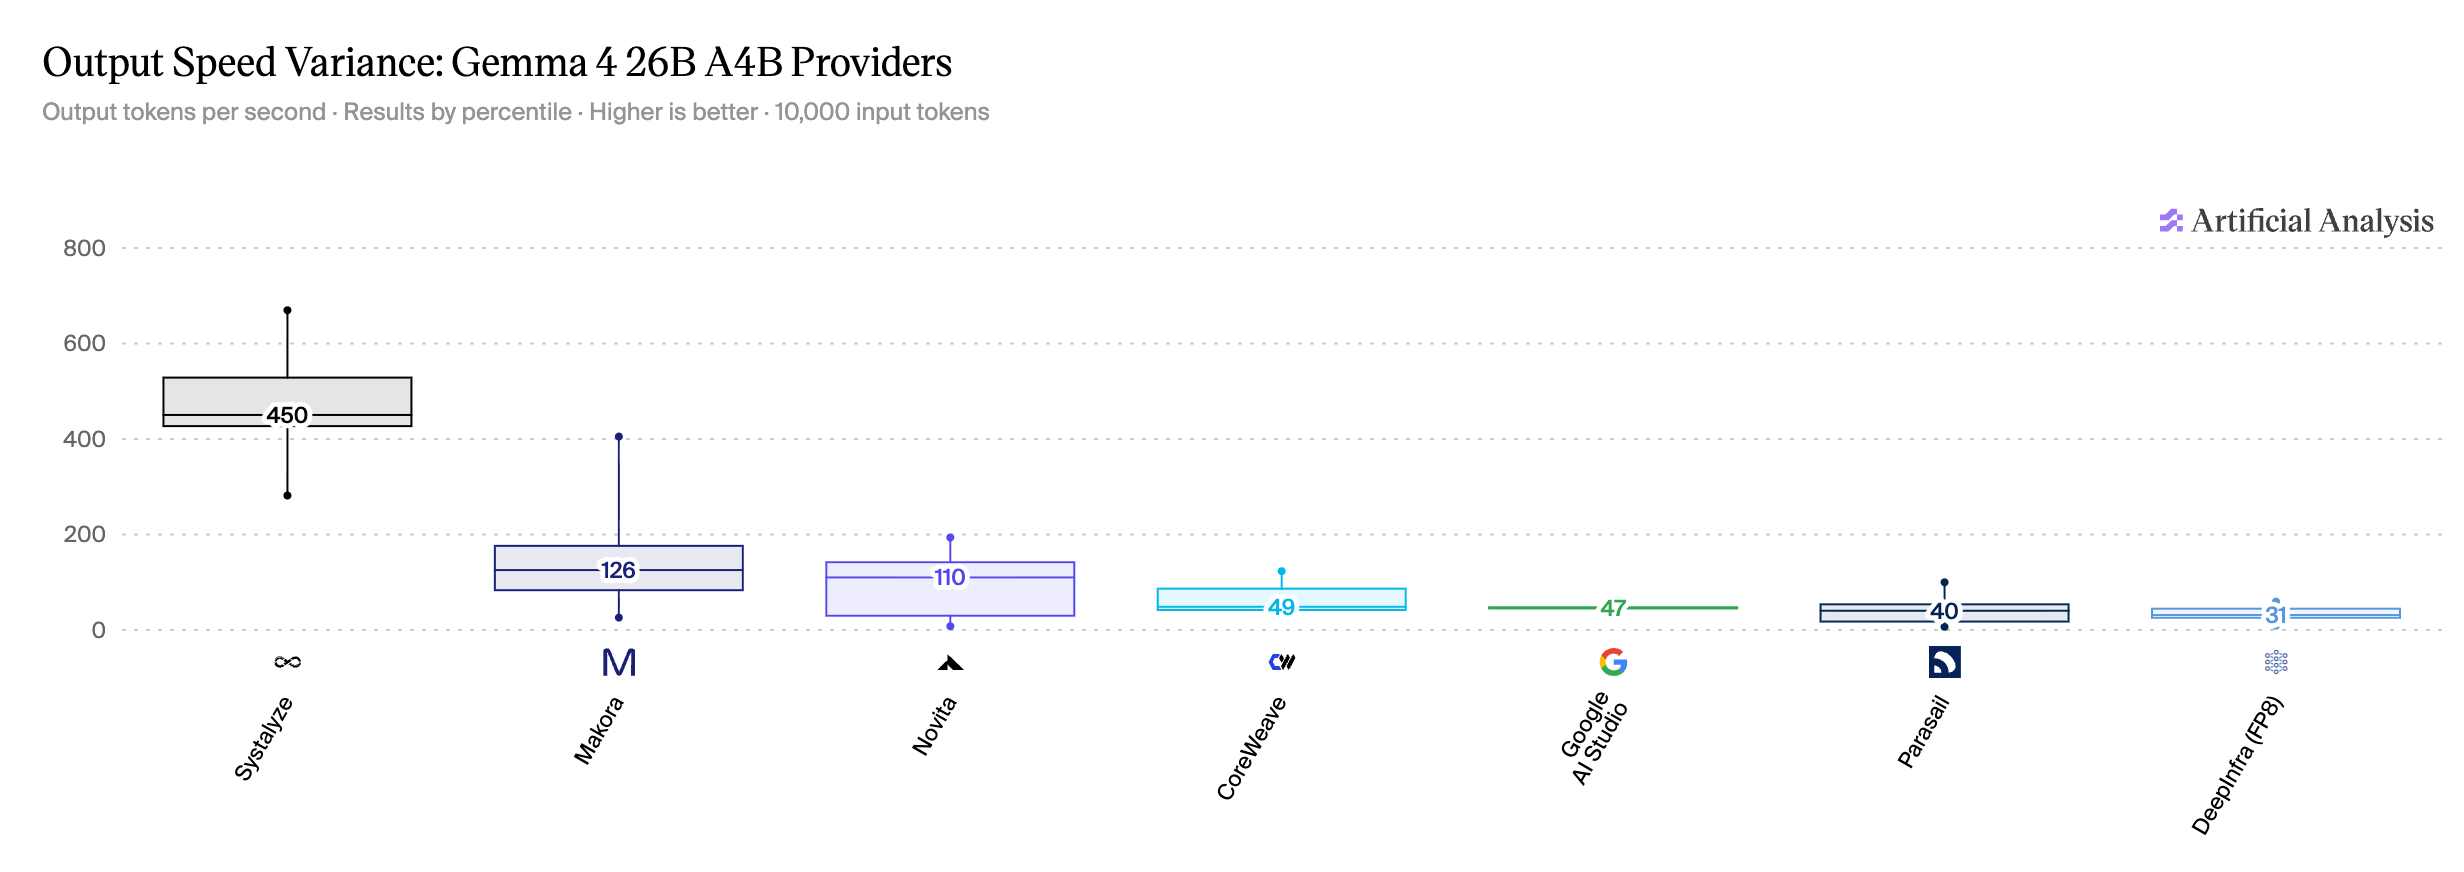
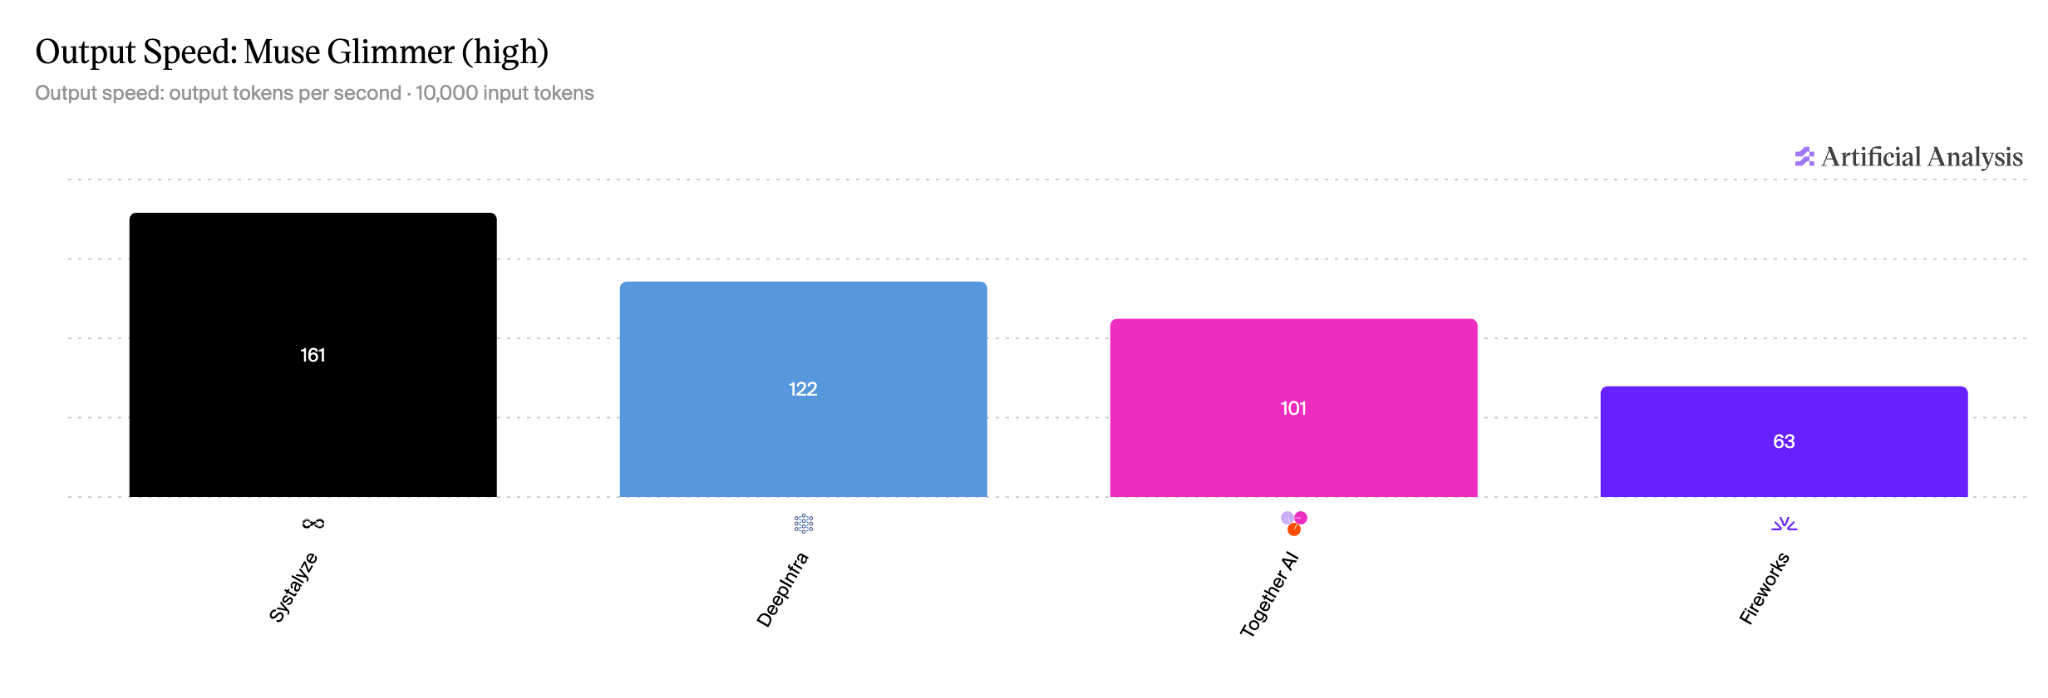
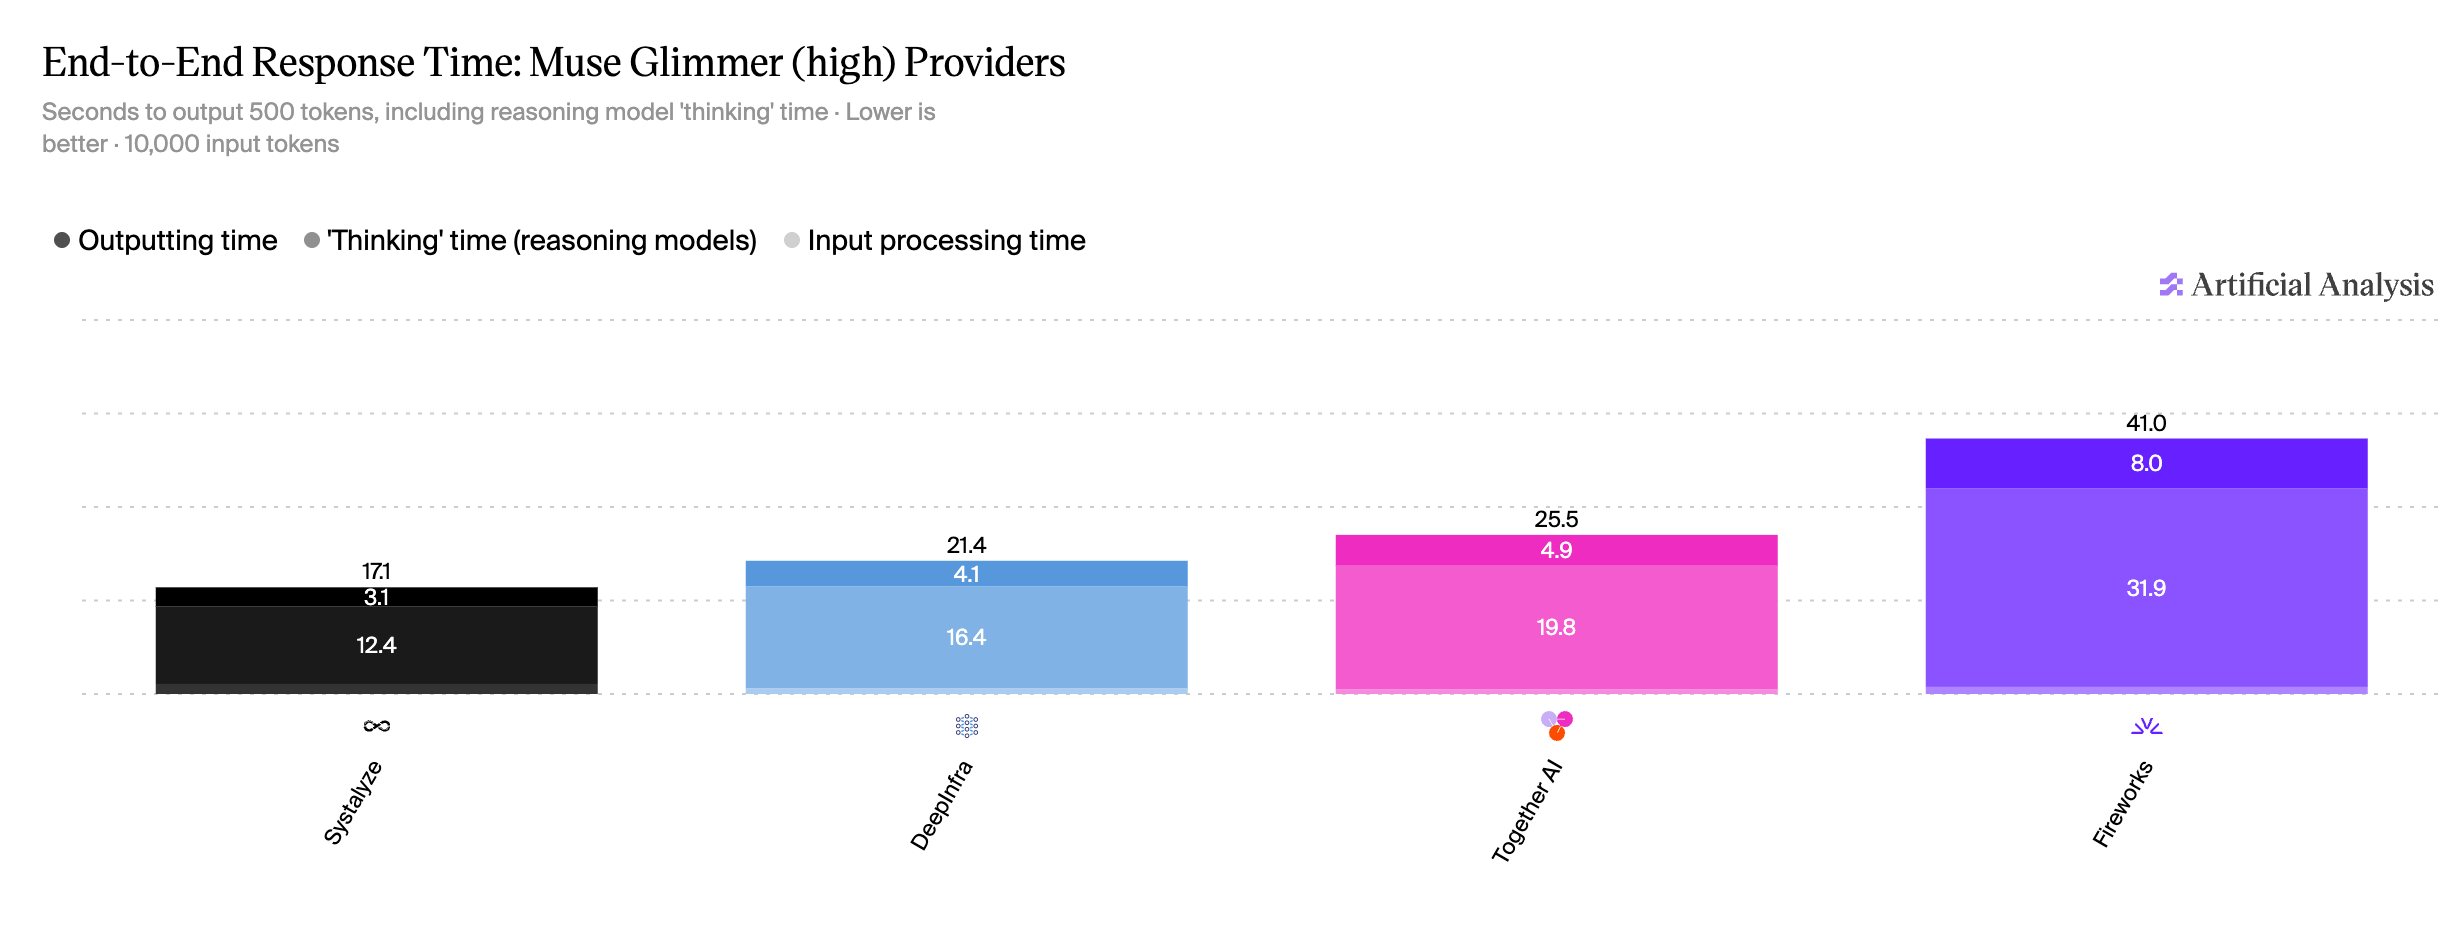
Output speed. How many tokens per second the model produces once it starts writing, measured with a 10,000-token prompt. This is raw generation speed. Higher is better.