Blog.
Engineering notes, benchmarks and open-source releases from the Systalyze team.
September 25, 2026 · Benchmarks
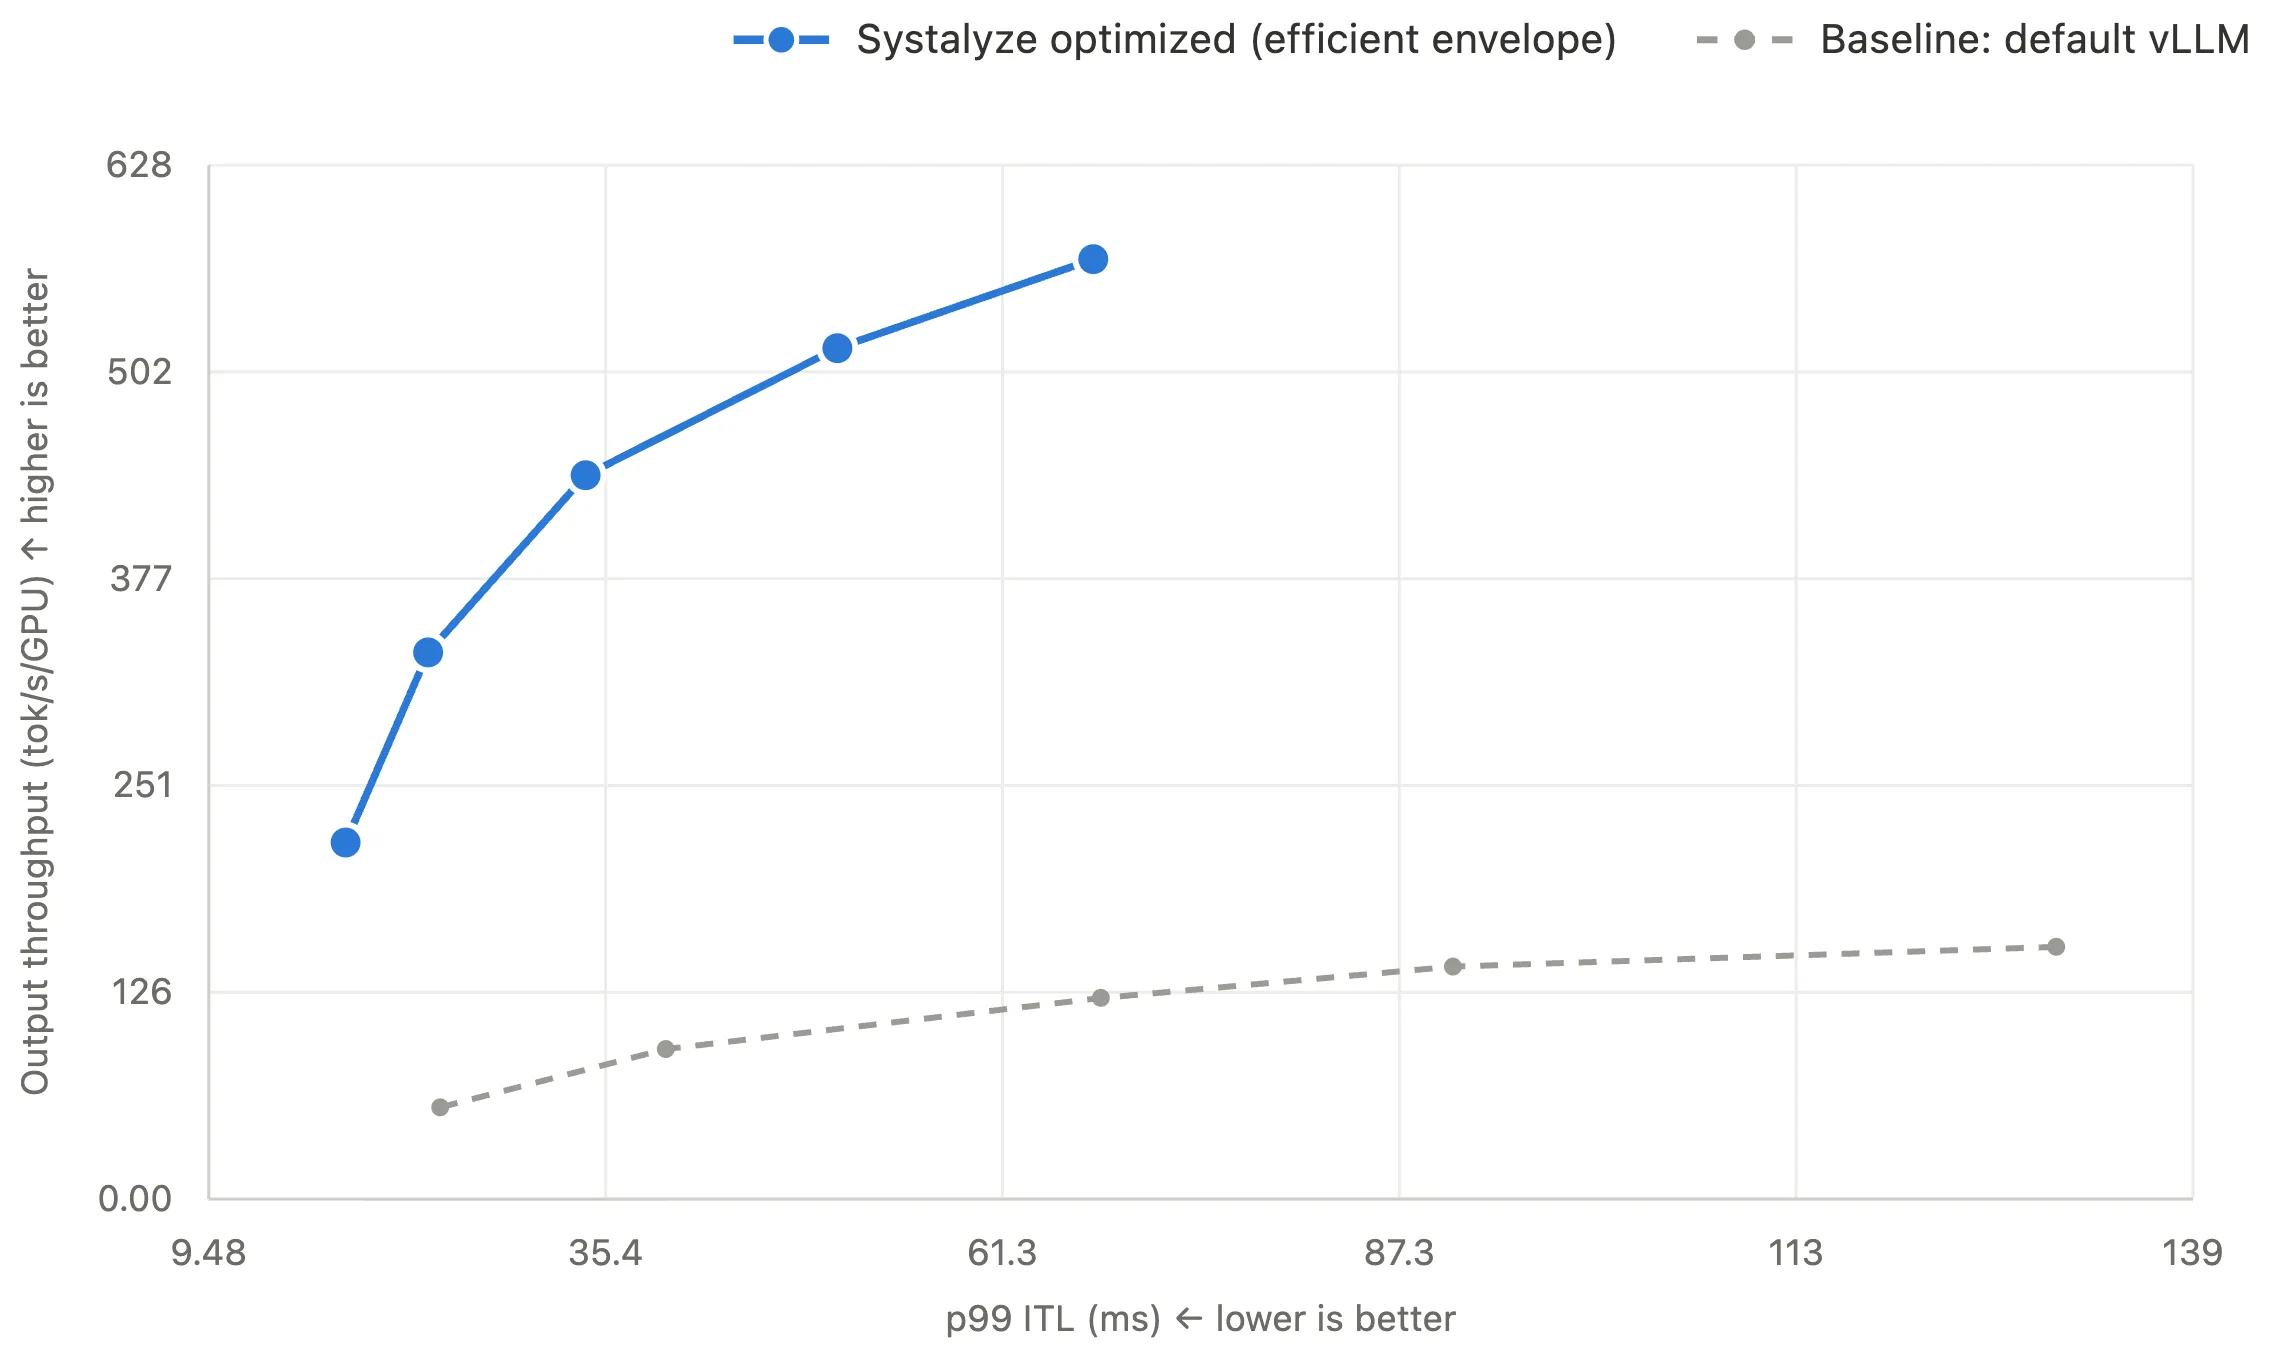
Systalyze Pushes the LLM Inference Frontier: Up to 10× Faster Serving
How Systalyze composes serving optimizations across Gemma 4, Nemotron and Qwen3-32B, achieving up to 10× faster serving and cutting cost per output token by up to 73%.
Systalyze · 5 min read
All posts
- Systalyze Pushes the LLM Inference Frontier: Up to 10× Faster ServingHow Systalyze composes serving optimizations across Gemma 4, Nemotron and Qwen3-32B, achieving up to 10× faster serving and cutting cost per output token by up to 73%.
- Your GPU dashboard is lying to youWhy nvidia-smi and DCGM overstate GPU utilization, and how Utilyze measures it accurately in production.